Bitcoin full node and query server
Feb 15, 2023
View in context in the libbitcoin Slack #general mirror.

evoskuil09:09
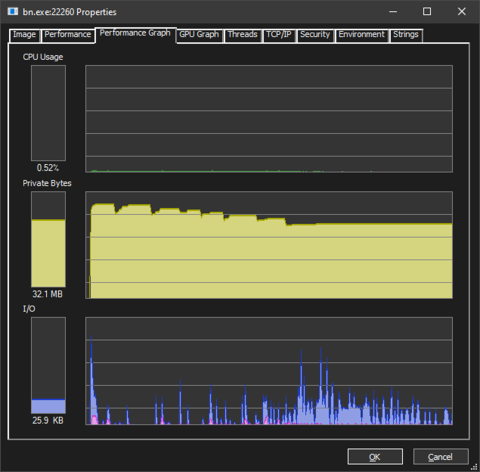
Quite a difference also in terms of useful work earlier in the run (vs. this one from a few days ago). I've moved the blocks of address validation from the session (central strand) to each channel (independent strand per channel). Strands of execution are non-concurrent, but concurrent vs. different strands. So this allowed the work to spread out nicely. This is what will happen with tx/block loads as well.
(edited)