
Bitcoin full node and query server
Oct 19, 2024
View in context in the libbitcoin Slack #general mirror.

evoskuil03:35
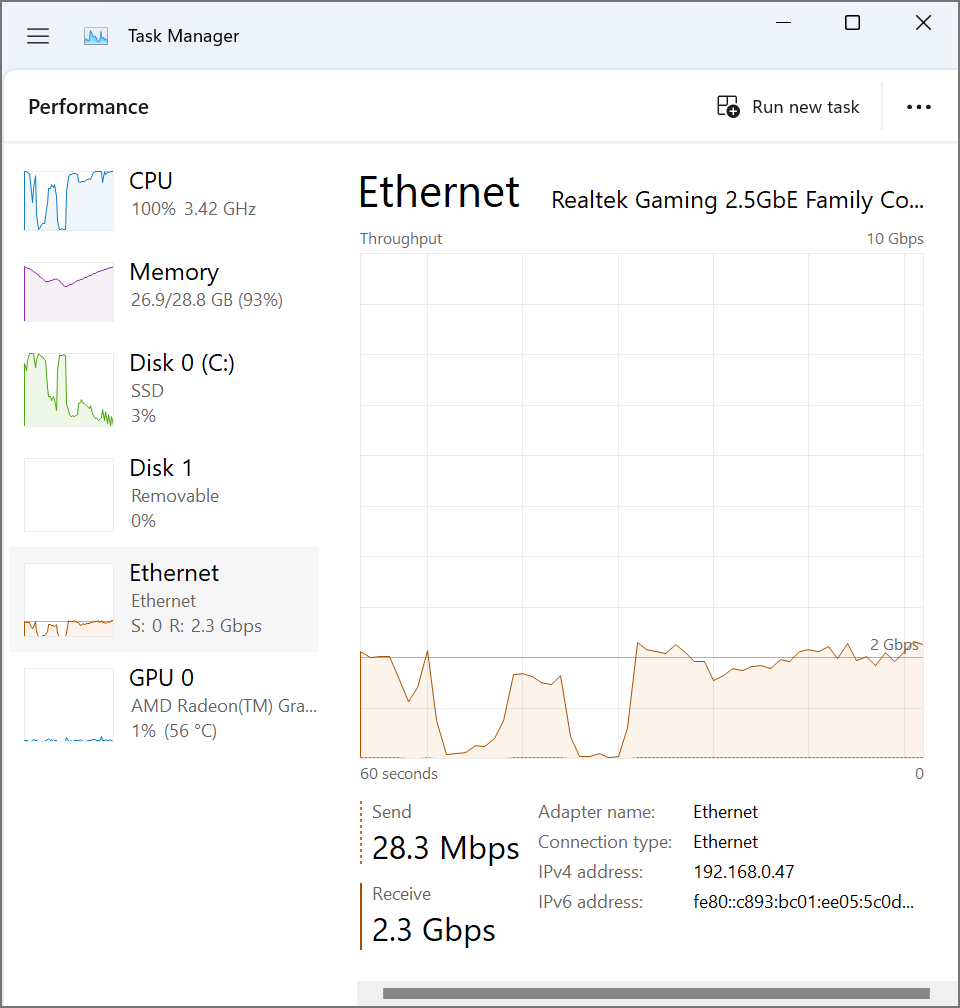
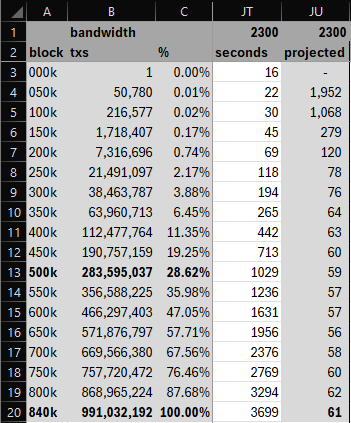
I just completed my first sync on a new $365 Windows mini PC (32 GB RAM, 16 dual cores). It slightly outperformed my big machine (256 GB, 32 dual cores) at 61 minutes to block 840k. And it's capable of AVX512 and SHA-NI, which will make it even faster once those are compiled in. I don't see any reason to work toward lesser machine support given that this is so cheap, and will continue to drop in price.
🔥 2❤️ 1🎉 1
12 replies · jungly, evoskuil, cguida · last Oct 19, 2024

evoskuil13:14
Each mini thread is 62% faster than big machine threads, so 40% of the big machine processing power. The mini makes up for the difference by a much higher utilization (close to 100% vs big at around 35%). That nicely shows the implementation scaling.
evoskuil13:16
The most extraordinary aspect however, is the complete lack of mmap thrashing - even with big machine config. This has to be a consequence of the 2x faster RAM and 2x faster SSD, since the RAM is only 12.5% of the big machine.
(edited)evoskuil13:18
There may also be a benefit from Windows 11 vs 10, since mmap is just a layer over Win32 APIs.
evoskuil14:11
Yes, I did. This is with a “milestone” of block 840,000 - so comparable to Core’s “assume valid”.
However, this also includes a full bidirectional constant time index for all chain objects (Core has the option to index tx hashes).
evoskuil14:12
Also this was with no config tuning (I used my big box config) and no SHA-NI and no AVX512. Also note that libbitcoin contains no C code and no Assembly, 100% C++.
evoskuil14:14
There’s still work to do, I try to not overpromote. We are presently working on full validation optimization. That was struggling on smaller machines due to mmap thrashing. It may turn out that we can just ignore that by setting this as min spec.
🔥 1
evoskuil14:16
But it’s a great sign. What I have told people for some time is that the performance problems people see are largely due to bitcoind architecture, not an inherent problem of capacity.
(edited)