Bitcoin full node and query server
Mar 10, 2025
View in context in the libbitcoin Slack #general mirror.

evoskuil23:32
Given our actual hashmap conflicts (posted above), filter size, and bloom
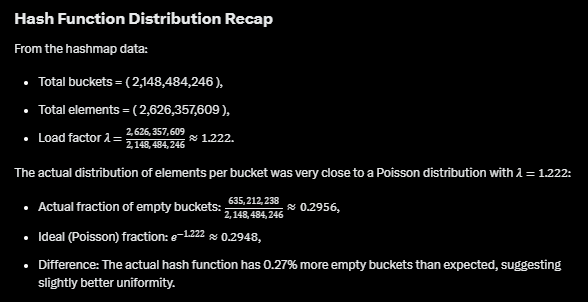
k value (e.g. 7), we can project the false positive rate. The actual hash function values present almost a perfect Poisson distribution (based on the use of sha256 values), but not perfectly (due to mixing in the point index). And in fact the uniformity is better than Poisson: