
Bitcoin full node and query server
Mar 19, 2025
View in context in the libbitcoin Slack #general mirror.

evoskuil05:56
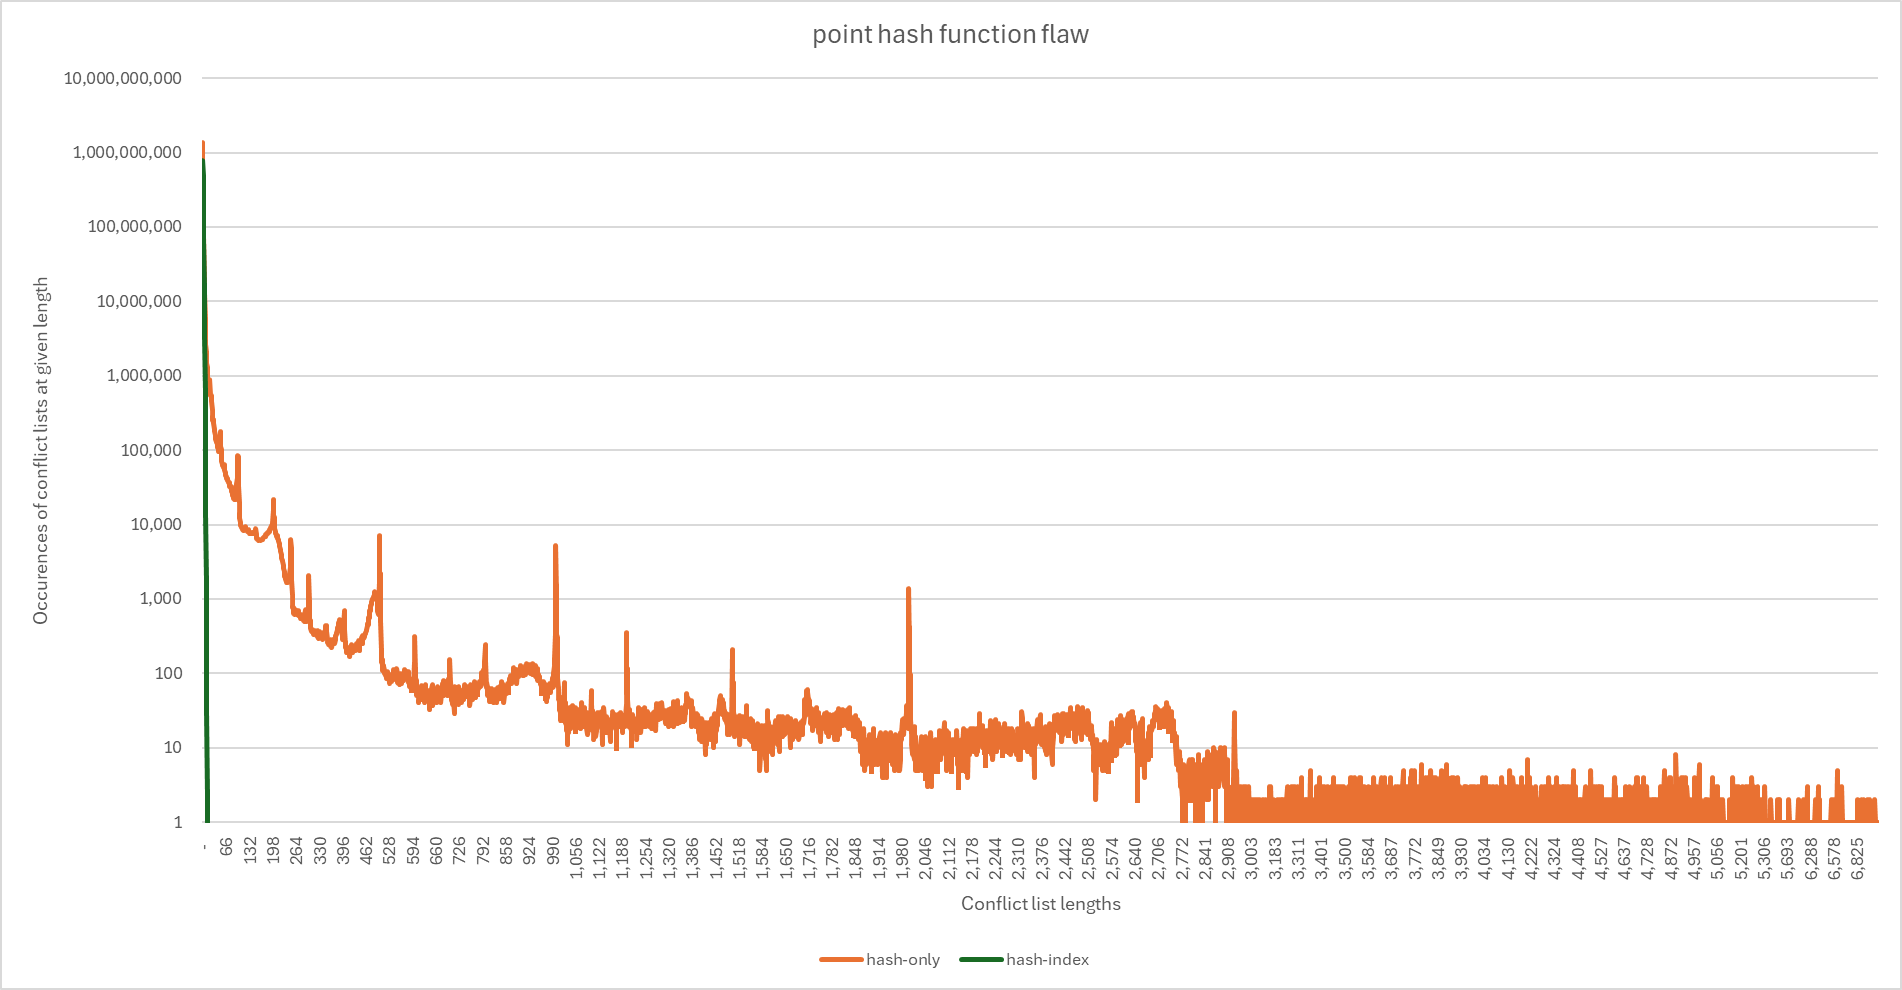
I've discovered that the point table hash function was not as expected, but that the previous bucket scans were reporting results as expected. The proper distribution is shown in green, actual distribution in orange. I haven't had a chance to measure the cost yet, but I expect it was significant. In other words, fixing this should yield a significant improvement - before even applying the above hashmap optimization.
👀 1