Bitcoin full node and query server
Aug 6, 2026
View in context in the libbitcoin Slack #general mirror.

evoskuil22:05
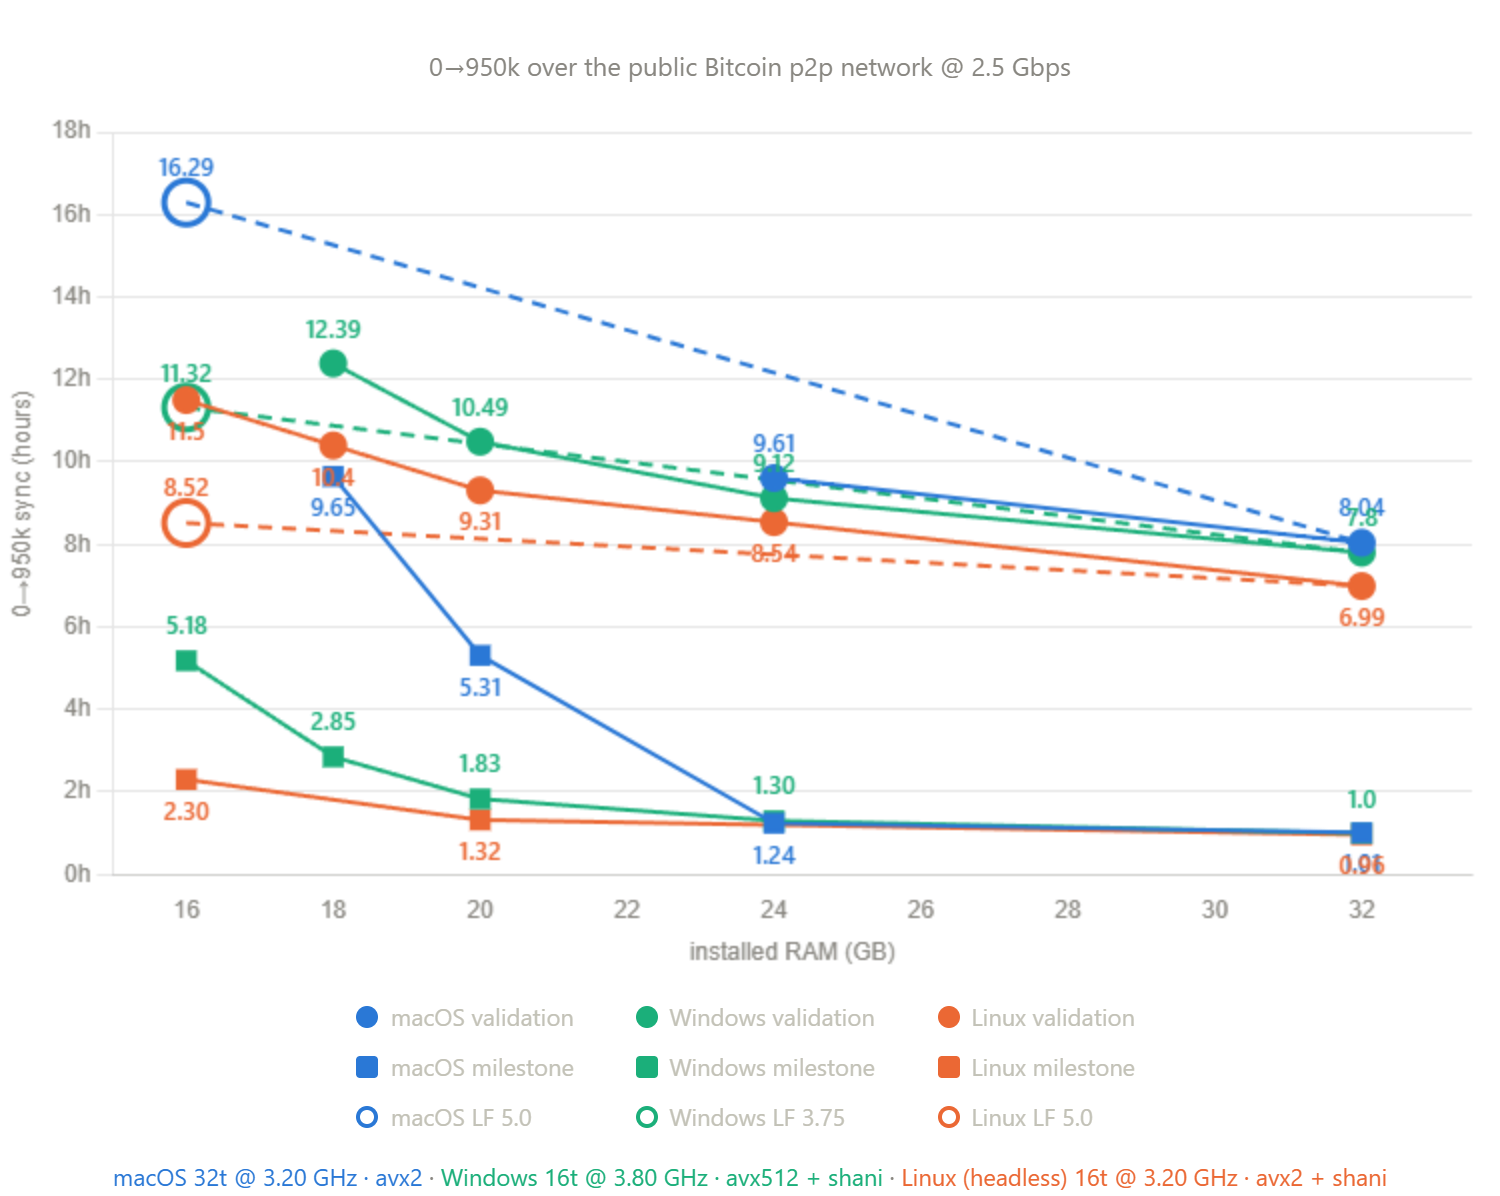
bigmac was grinding through its full validation steadily until it was jetsam-killed at around 850k. I've projected a completion along its curve because it wasn't parabolic - it was steady.
Notice that the leftmost solid circle shows the point after which the LF2.5 runs went parabolic with latest optimizations. The open circles show the same code running at an increased LF. For Windows the LF3.75 was better than LF5.0, since the header residency problem is less pronounced for it and the higher LF increases body paging.
So you can see that we have a pretty clear pattern. The different mmap implementations and underlying support handle memory pressure differently. In full validation by 32GB this is mostly phased out, and similarly for milestone by 24GB. Yet we are avoiding thrashing down to 16GB at least, with the exception of macOS, which got close. I suspect the duplicate probing starts to hurt in this regime, which I'll verify at some point.
The LF impact implies that we should tune the heads given a default store creation, and vary that by platform.
There is damage on high RAM platforms in Linux, as a consequence of aggressively shedding body pages. I've disabled that above 32GB but I don't have a platform to verify it.
The next round of tests will hit milestone with the latest optimizations and LF variations. It's possible and I've seen a couple of times, that optimization for one scenario hurts another, but at this point I believe it's optimal across validation and milestone. I expect that, as with the validation runs, the LF increase will significantly bend down the low end of the milestone curves, as the heads are only required for reads, and the increased LF hurts reads, but we don't read much in the big heads for milestone. So it's more like free RAM at no cost. Ideally those would entirely flatten to network limited all the way to 16GB.