Bitcoin full node and query server
Sep 28, 2026
View in context in the libbitcoin Slack #general mirror.

evoskuil17:30
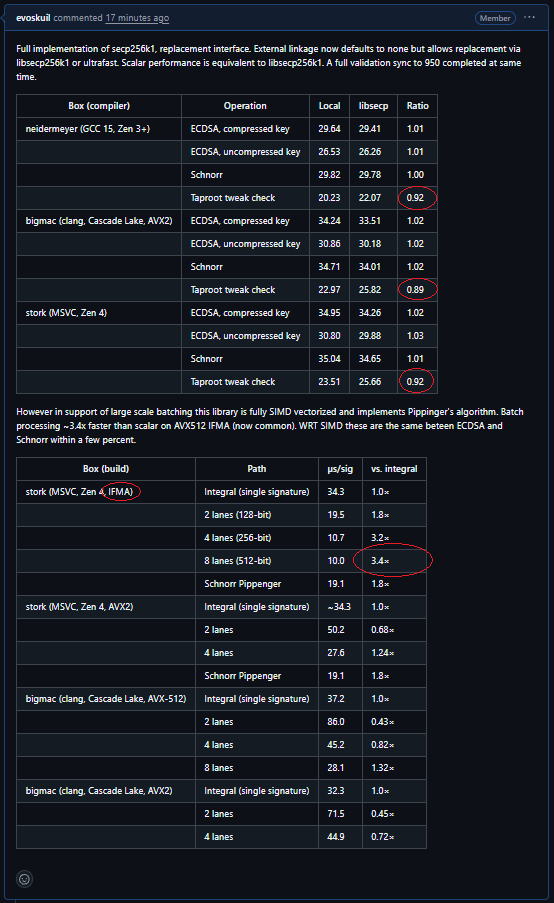
We're
(edited)10% faster at Taproot Tweak (part of script verification) because we compute the tweaked key as tweak·G + P with a single point addition. libsecp256k1 doesn't implement batch vectorization via SIMD, so we are are 34x faster at CPU batching on AVX512. Other configurations show 0-2% slower on scalar signature verify, but there's still a little room left to squeeze that out.