
Bitcoin full node and query server
March 2026
Archive of the libbitcoin Slack #general channel.
Monday, March 2, 2026

evoskuil14:17
micron.com
Micron 9650 is the world’s first PCIe Gen6 SSD in mass production, delivering breakthrough data center performance, efficiency, and AI workload acceleration.
🫠 1
Wednesday, March 4, 2026
evoskuil19:45
I haven't actually done this in at least 5 years, since the current v4 architectural work began... but I took a few minutes today to total up lines of code. I excluded obsolete v4 libs (protocol, blockchain, client).
https://ghloc.vercel.app/libbitcoin/libbitcoin-system?branch=master    188,314
https://ghloc.vercel.app/libbitcoin/libbitcoin-database?branch=master   41,925
https://ghloc.vercel.app/libbitcoin/libbitcoin-network?branch=master   629,718
https://ghloc.vercel.app/libbitcoin/libbitcoin-node?branch=master       20,371
https://ghloc.vercel.app/libbitcoin/libbitcoin-server?branch=master    153,149
                                                                     1,033,477

https://ghloc.vercel.app/libbitcoin/libbitcoin-build?branch=master      30,380
                                                                     1,063,857

https://ghloc.vercel.app/libbitcoin/libbitcoin-explorer?branch=master   64,764
                                                                     1,128,621
So server is over 1 million loc, mostly c++ (cpp/hpp/ipp).
evoskuil20:11
Network is heavy due to wolf embed, which is 569,206 loc. A small amount of this is ours, but not material. That reduces network to 60,512, and total to 559,415.
We also embed qrencode in system, which is only 5,073 loc. That reduces system to 183,241 and total to 554,342.
The electrum_v1 and bip39/electrum_v2 word catalogs are 23,862 loc in system. Removing that as well leaves system at 159,379 and total at 530,480.
evoskuil20:28
Server is showing 122,609 loc from .svg files in docs, which reduces that to 30,540 and total to 407,871.
Also, we prob don't need to count build more than once, or even the generated artifacts at all. So counting the build repo and then just cpp/hpp/ipp files is prob sufficient. We have almost no c/h files, and nearly all of that is wolf/qrencode.
evoskuil20:39
Reducing this to just cpp/ipp/hpp only, less word dictionaries, plus the build repo gives a much tighter picture:
system        143,810
database       32,857
network        47,870
node           10,779
server         15,740
              -------
total server  251,056

explorer       48,009
build          30,380
              =======
total stack 329,445 (edited)Given the huge amount of increased functionality, and increased test, with the material overall reduction in lines of code, you can see how much density is paying off. Though we pay for it in build time.
👍 2
evoskuil21:50
In a rough comparison to Bitcoin Core, their one repo embeds both leveldb (3rd party dependency) and libsecp256k1 (which we also use but don't embed). They also implement a full wallet. While we have wallet code in system, our comparable client interface code is in explorer, and isn't a wallet, and BC has common code for wallet shared with the node as well. So I use this filter to count its loc:
(edited)cpp,.hpp,.c,.h,.ipp,.cc,!secp256k1,!wallet,!leveldb
Which comes out to 240,172 - most directly comparable to our 251,056, which excludes all build artifacts in both cases. If you include its /wallet directory and our explorer, it's 270,907 loc of code to our 251,056 + 48,009 = 299,065. Roughly speaking, libbitcoin is about 10% more loc in c/c++ than Bitcoin Core. In some ways we have more functionality (e.g. Electrum server), and others we have less (e.g. no tx pool).Thursday, March 5, 2026

eynhaender16:13
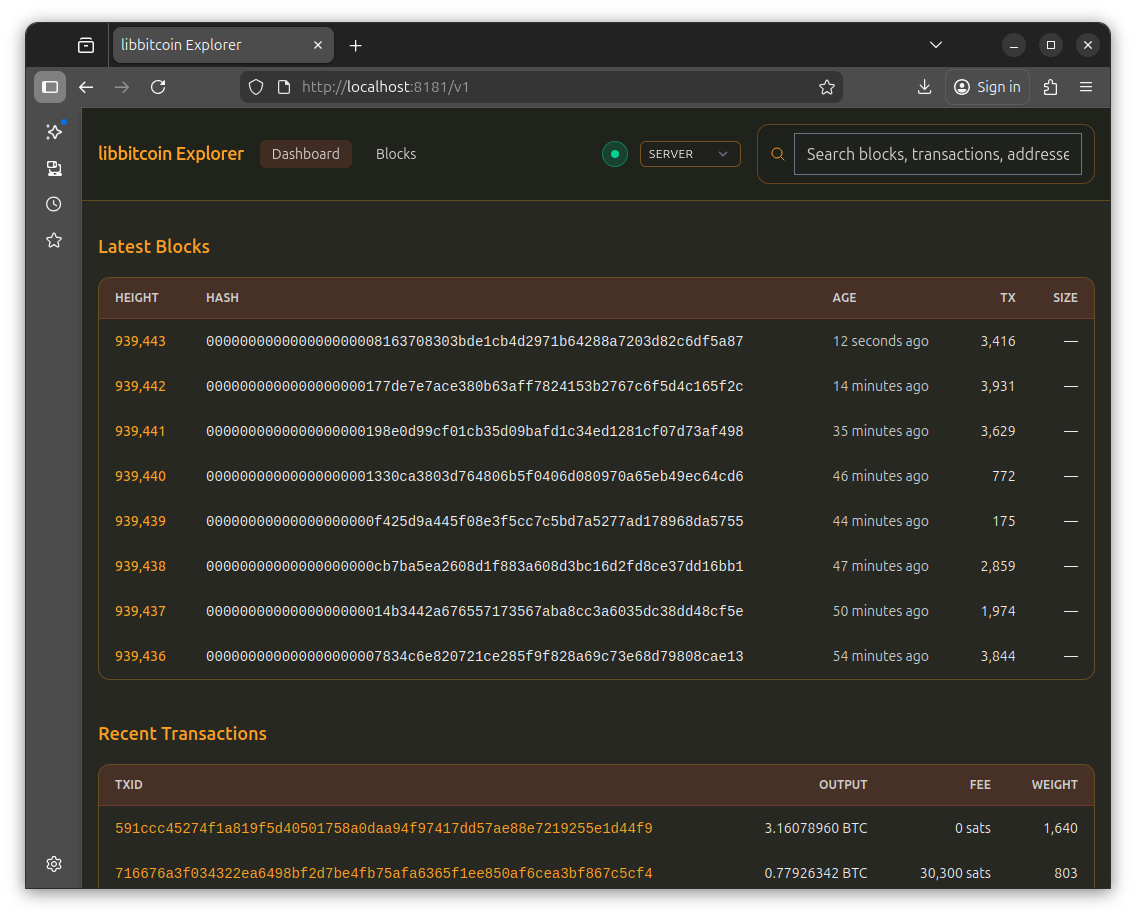
Just configure it this way and connect to this URL in your browser
# ----------------------------------------------------------------------------------------- Client Server Settings - Blockchain Explorer
[native]
bind = 0.0.0.0:8181 # All IP v4
bind = [::]:8181	# All IP v6
connections = 10
1 reply · Marnix · last Mar 05, 2026
Huddle with pmienk, eynhaender, Marnix, Rowan Voskuil · 67 min16:56
3 replies · Rowan Voskuil · last Mar 05, 2026

Rowan Voskuil18:10
@Marnix I forgot to mention but to get address query's to function you need the address tables enabled. Also you should enable turbo.
[database]
turbo = true

filter_bk_size = 14,000,000
filter_bk_buckets = 900,001

filter_tx_size = 2,700,000,000
filter_tx_buckets = 900,001

address_size = 30,000,000,000
address_buckets = 1,315,297,540
👍 2
My config as a example
This also requires a new store so delete the database and resync if you make this change.
Wednesday, March 11, 2026
Thursday, March 12, 2026
Huddle with pmienk, evoskuil, eynhaender, Marnix · 107 min15:55
Monday, March 16, 2026
evoskuil00:51
In the last couple days I've completed most of the alternate json serializations for bitcoind (and by pass-thru, electrum) objects. The generalization makes it easy to add other forms as well. It's mostly just another set of annotations over the objects, just needed a context to hang that on. I've left out of the static object serializations anything that is not a property or computable from properties of the objects. In other words state that is out of context (there is a bunch of this in bitcoind objects). That just gets injected (e.g. by the server) into the JSON DOM after it's constructed from a chain class instance.
I still have to provide the bitcoind script serialization (ughly). We have long supported deserialization of that (or our own) transparently, but we never serialize to bitcoind. That was mainly to allow script test vector portability. But I'll add a flag to the script::to_string(bool bitcoind) serializer and that will be sufficient for the json serialization, because in both cases the script is just a single formatted string.
I also updated the
(edited)witness_address class for v1 (taproot) addresses, which along with payment_address allows parse/serialize of all address formats serialized by bitcoind (yeah, why does a node construct payment addresses from txs for callers 🤷🏻♂️).🎉 1
Wednesday, March 18, 2026

pmienk20:53
cmake refactor:
https://github.com/libbitcoin/libbitcoin-build/pull/401
https://github.com/libbitcoin/libbitcoin-system/pull/1797
https://github.com/libbitcoin/libbitcoin-database/pull/731
https://github.com/libbitcoin/libbitcoin-network/pull/744
https://github.com/libbitcoin/libbitcoin-node/pull/977
https://github.com/libbitcoin/libbitcoin-server/pull/661
Contains breaks to version3 support from removal of ICU.
Please let me know if anyone feels capable of review, otherwise this evening I will begin merging iteratively to assure CI passes.
🔥 1
Oh, feel free to view my
cmake-icu-removal-integration branches as verification that the changes work up the stack - only relevant changes should be to reference my own repos up/down the dependency tree.Thursday, March 19, 2026
Huddle with pmienk, eynhaender, Marnix, evoskuil, parsevalbtc · 73 min15:55
Monday, March 23, 2026
Tuesday, March 24, 2026
Wednesday, March 25, 2026

Adi Shankara05:21
Hi all. This is Adi, program lead at Summer of Bitcoin - a non-profit that runs a global internship program for university students to work on bitcoin open-source software.
In 2024, Tanay and Shashank contributed to libbitcoin under the Summer of Bitcoin internship program. We'd love to have libbitcoin again this year!
What’s different this year: AI has made "starting" a hundred ideas easy. The bottleneck is still shipping - correctness, tests, benchmarks, reviewability, docs, and getting changes into the hands of real users. This year's application process was geared towards selecting interns who use AI as a force multiplier but can still do the hard last-mile work to get something safely merged and actually adopted.
Project ideas can be classic (core dev / infra / testing / performance / DevEx), but we’re also explicitly excited about AI-native directions like:
- agent-facing interfaces (e.g., MCP/tool-style APIs) so dev agents can discover and use the project
- UX/UI + design research work to make things easier for end users and developers
- fun/peripheral/risky-exploratory prototypes - as long as they still ship durable artifacts (tests + docs + demo)
In brief: mentors propose 1–3 project ideas, candidates submit detailed proposals, you select the best fit, and SoB pays those selected with a stipend in BTC. If you’re open to it, I’m happy to share more details!
(edited)1 reply · Adi Shankara · last Mar 27, 2026
Adi Shankara04:10
just bumping this up! Any interest in taking on young talent, getting more features shipped and potentially building a contributor pipeline? we're looking to wrap up a final project list by next week. happy to answer any questions!
👋 1
Thursday, March 26, 2026
Huddle with pmienk, evoskuil, Marnix, Rowan Voskuil, eynhaender · 131 min15:54
1 reply · evoskuil · last Mar 26, 2026
evoskuil22:02
Someone was monitoring the slack:
https://x.com/9to5mac/status/2037273705156391027?s=20
X (formerly Twitter)
Apple has confirmed to @9to5Mac that the Mac Pro is being discontinued with no plans for future hardware
It's also no longer available on Apple's website as of Thursday afternoon
The end of an era 🧀
😲 1
Friday, March 27, 2026
Saturday, March 28, 2026
evoskuil04:48
I've verified blocks-out (and headers out) against a local core v28.0 node. Had one initial issue (an inverted operator), but then kept having what appeared to be race conditions. After digging into it, it turns out core is sending overlapping
(edited)getdata (block) requests. I verified this on our end but also in their code.
Since we have to deal with them, we have to treat this as allowed behavior. So I made it configurable. You'll be able to watch the overlapped I/O errors cause core nodes to drop by changing config 🙂. Working well now, passing block 375k on one manual connection from core, with no drops or delays.
I'm perf-logging our block retrieval time, and had to change the scale to microseconds. Adding up all times the total retrieval time is 29% of the total time. If core took the same time to read and serialize the block as we took to deserialize and write it, the run at that point (300k, or ~5% of the chain) would be 15 minutes, but it's about 53 minutes. This machine syncs the entire chain off the Internet in 53 minutes.😞 1
evoskuil15:35
Ran a full default sync from bs->core. I forget to extend the channel timeout, which defaults to 60 minutes, so every 60 minutes there's a channel restart (unclear why one time it took 11 minutes to reconnect). Full blocks still averaging around
50ms retrieval (unoptimized). 12 hrs passing block 830,000 which is consistent with syncing Core on this machine over the Internet. In neither case is it anywhere close to network or other resource limited. Presently with both nodes running on the same machine, CPU is < 5% (basically idle).
	Line    785: 2026-03-28T03:19:18Z New manual v1 peer connected: version: 70015, blocks=942521, peer=0
	Line 339281: 2026-03-28T04:19:20Z New manual v1 peer connected: version: 70015, blocks=942521, peer=1
	Line 424963: 2026-03-28T05:19:22Z New manual v1 peer connected: version: 70015, blocks=942521, peer=2
	Line 486615: 2026-03-28T06:19:23Z New manual v1 peer connected: version: 70015, blocks=942521, peer=3
	Line 548201: 2026-03-28T07:19:29Z New manual v1 peer connected: version: 70015, blocks=942521, peer=4
	Line 598700: 2026-03-28T08:19:30Z New manual v1 peer connected: version: 70015, blocks=942521, peer=5
	Line 648664: 2026-03-28T09:19:36Z New manual v1 peer connected: version: 70015, blocks=942521, peer=6
	Line 693961: 2026-03-28T10:19:37Z New manual v1 peer connected: version: 70015, blocks=942521, peer=7
	Line 735774: 2026-03-28T11:19:39Z New manual v1 peer connected: version: 70015, blocks=942521, peer=8
	Line 774706: 2026-03-28T12:19:41Z New manual v1 peer connected: version: 70015, blocks=942521, peer=9
	Line 803976: 2026-03-28T13:30:45Z New manual v1 peer connected: version: 70015, blocks=942521, peer=10
	Line 814830: 2026-03-28T14:30:52Z New manual v1 peer connected: version: 70015, blocks=942521, peer=11
(edited)
evoskuil15:40
There were early claims by some people that our indexed block storage would result in long block query times, slowing IBD. This was predictably not true, because writing is more costly than reading, and we write easily the entire store in 45 minutes. But this just reinforces that fact. Even with full block object reconstruction from the relational store, where each op in each script is stored as an object with a shared pointer (for push data), and then wire serialization from that object model, it is much faster than necessary. And reducing the query to just construct the wire serialization directly will easily cut this in half.
Sunday, March 29, 2026
evoskuil04:35
Getting close to 900k core's block requests have slowed to a crawl. bs is still popping out blocks at around 50 ms, but requests by core are now seconds apart.
evoskuil15:06
Finished at 26 hrs to 942,728 and about 22 hrs to 900,000. That's about the same as syncing core off the internet on this machine maxi)
bs still serving full blocks around 50ms at the end:
block_usecs......... 44074 16345
block_usecs......... 54323 16346
block_usecs......... 53774 16346
block_usecs......... 74 16347
block_usecs......... 50587 16347
block_usecs......... 67464 16349
block_usecs......... 60572 16349
block_usecs......... 68912 16349
block_usecs......... 65131 16349
block_usecs......... 46967 16350
block_usecs......... 52613 16350
block_usecs......... 51820 16350
block_usecs......... 47525 16350
block_usecs......... 38512 16351
block_usecs......... 25681 16351
block_usecs......... 38539 16351
block_usecs......... 63661 16352
block_usecs......... 60718 16352
block_usecs......... 71986 16352
block_usecs......... 52539 16352
block_usecs......... 12967 16352
block_usecs......... 34581 16353
block_usecs......... 878 16353
block_usecs......... 30838 16354
block_usecs......... 52557 16354
block_usecs......... 43162 16354
block_usecs......... 43071 16355
block_usecs......... 55364 16355
block_usecs......... 70396 16356
block_usecs......... 26511 16356
block_usecs......... 70550 16356
👌🏻 1
evoskuil15:15
bs shutdown in 30 secs (after paging through the full store). Core shutdown took 4.5 minutes (dbcache=32000).
(edited)evoskuil15:30
I spent yesterday implementing the direct translation from the store for header, block, and tx, into wire serialization. The low level store getters are provided a stream reader, so I just pass in a stream writer reference with the getters and read directly into the output stream. Since the writer is just an interface the caller can pass in a hex stream writer, which allows for streaming directly to hex (text) for the interfaces that require it (like electrum/bitcoind json-rpc). We could also pass a socket writer reference and pass directly from the store into the socket buffer.
evoskuil23:17
Just completed the optimized block (and tx/header) wire serialization queries and hook into the block-out protocol. So instead of populating a block object and serializing it, we are reading it directly from the store into wire serialization, and copying it into the write buffer. Savings in query time in the first 125k blocks is about 28%. These are tiny blocks, so I didn't expect to see much change. As they get 3 orders of magnitude larger the savings should go up dramatically. Mind you, it was already fast 🙂.
Monday, March 30, 2026
evoskuil00:30
Looks like it's stabilizing around 35% savings. Can prob squeeze a little more out of that by avoiding intermediate allocations, but prob not worth the effort right now. That's a big bump for a day's work.
🔥 1
This provides some of the work for the optimized block/tx reads from the wire to the store as well (the other direction). That will materially improve sync time whereas this part was not related to sync.
(edited)evoskuil01:45
[Somehow I swapped links for the endpoint I was testing with, so the block was small, so deleted those posts.] The optimization is more significant with warm queries, looks like about 1/3 the time vs. 2/3 in the cold queries above. The 1mb warm http block query is down to 13ms server response time:
http://localhost/v1/block/height/942671?format=data
(edited)evoskuil01:54
Whereas the populated block queries are around 30ms. So more than cut the time in half on warm queries.
Added a node setting that allows libbitcoin to supply blocks to peers that make overlapping block requests (defaults to true because this is a Core behavior). Otherwise the peer is dropped for protocol non-compliance.
[node]
allow_overlapped = true
(edited)
👌🏻 1
evoskuil23:07
Found a bs<->bs manual sync issue. Manual connections were not allowed to sync unless there were also outgoing connections, because the block chaser was disabled with zero outgoing connections (same with inbound connections when outbound is zero).
(edited)But I set up a few manual connections and now can sync in parallel between bs nodes.
evoskuil23:50
I'm now syncing from bs to another bs on 6 independent bindings (3 ipv4 and 3 ipv6) in parallel and to a core node. And outbound to the interwebs at the same time.
(edited)Tuesday, March 31, 2026
evoskuil02:37
First time I've tried this. Two process, same bs.exe with independent config files, stores on independent SSDs. Left is serving, bound to all ipv4 and ipv6 on default port. Right is manually connecting on ipv4 and ipv6 for localhost and two physical adapters (6 connections). Left has 100 outbound and 100 inbound connections enabled as well. Also running a core node connected via manual localhost. Left is just pumping blocks and other message traffic and Right is balancing work across 6 channels. Allowed deviation (sd) is set to zero on Left, so no dropping of slow/stalled connections (optimal given all are against the same process).
evoskuil15:55
2.24 hrs to sync from one SDD to another over 6 channels on the same machine, while publicly connected on the other. So about twice the time it takes to sync one process over the internet on the same machine.