
Bitcoin full node and query server
April 2026
Archive of the libbitcoin Slack #general channel.
Wednesday, April 1, 2026

evoskuil04:44
Great progress on the
electrum endpoint today. Updated all tests with version conditions, for initial availability, additions, behavior changes, and obsolescence. Implemented server.features and server.ping methods. Improved electrum test harness and expanded coverage.
Also verified bs<-bs and bs<-core full chain and multi-channel sync on windows and linux and on manual and inbound channels (most sync we test has been multiple outbound channels over the Internet). Performance looks excellent. Getting close to being able to provide clean benchmarks for blocks out, with the expectation that we should be able to provide the full chain out as fast as we can sync it in.evoskuil17:58
Just adding more channels (12 vs. 6) to the single machine bs-bs sync reduced the total 900k block milestone sync time from 2.24 to 1.77 hrs.
(edited)2 replies · pmienk, evoskuil · last Apr 01, 2026
evoskuil18:02
The second SSD is slower, so that's part of it. But the change implies that concurrency had been the bottleneck. Each channel runs on its own strand, effectively limiting concurrency to 6 (or 12) threads on both ends. On a 100 peer internet sync it's limited to 16 network threads by default config. So I'll bump up the peer count to 16 tonight.
(edited)Thursday, April 2, 2026
evoskuil06:50
Electrum progress continues. Methods pertaining to
server, transactions, and headers are almost done and fully tested. The tx and package submission methods are fully implemented except for the actual submission (broadcast to the network). Just two methods left in server. Then it's mempool, fees, and addresses. All methods are stubbed in and invoke properly. The hard work in fees has already been done, mempool is simple, and addresses are a set of nearly-identical queries against the address index - which are similar to those in the native endpoint. I'd say 1-2 weeks to complete, with the notable gaps around mempool/submit.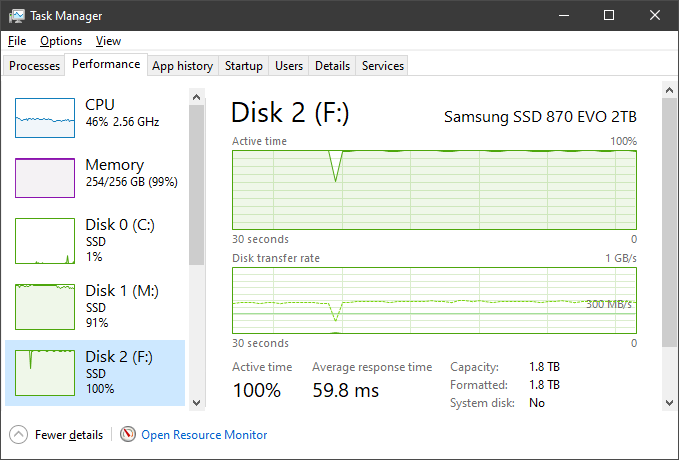
Chain is flowing from M:->F:
Huddle with pmienk, eynhaender, Marnix, Rowan Voskuil, evoskuil · 232 min15:56
1 reply · pmienk · last Apr 02, 2026

pmienk16:19
Script managing the build and installation of libbitcoin-server and its dependencies.
Script options:
--build-boost Build Boost libraries
--build-secp256k1 Build libsecp256k1 libraries
--build-src-dir=<path> Location of sources.
--build-obj-dir=<path> Location of intermedia objects.
--build-obj-dir-relative Use build-obj-dir as relative to project sources.
--build-config=<mode> Specifies the build configuration.
Valid values: { debug, release }
--build-link=<mode> Specifies link mode.
Valid values: { dynamic, static }
--build-full-repositories Sync full github repositories.
Default clones depth 1, single branch
--build-parallel=<int> Number of jobs to run simultaneously.
Default: discovery
--build-use-local-src Use existing sources in build-src-dir path.
--prefix=<path> Library install location.
Default: /usr/local
--verbose Display verbose script output.
--help, -h Display usage, overriding script execution.
cmake ${VERBOSITY_CMAKE} -LA "$@" "${BUILD_SRC_DIR/${PROJECT}/${RELATIVE_PATH}"
VERBOSITY_CMAKE="-DCMAKE_VERBOSE_MAKEFILE=ON"
pmienk23:28
huh, gcc must have a bug. I used clang to build past the boost beast fault i got in network. looked into the /bigobj windows switch - linux doesn't have that option or suffer the limitation, though there is a way to pass it when using gcc on windows.
Friday, April 3, 2026
evoskuil05:20
I discovered 9 obsolete (prior to current v1.6) electrum methods that weren't in the documentation, so I've added those to the interface, stubbed, and implemented dispatch. They are essentially redundant with the newer ones, but adds about a half day of extra overhead.
Build time is taking me more time than anything at this point, so it's looking like time to finally update my dev box.
Saturday, April 4, 2026
evoskuil06:04
More implementation and test on electrum endpoint methods today. Completed all but the address/scripthash methods (queries against the dedicated address table). Apart from there I just have the integration of the one fee estimation method base on the previously-completed fee estimator.
Sunday, April 5, 2026
evoskuil01:11
A full day of working off technical debt in libbitcoin-database. Queries are now rationalized and divided up into many smaller files. Still need to reorganize tests and includes.
Monday, April 6, 2026
evoskuil04:39
Finished up the tx population query, which populates previous outputs for unconfirmed txs and augments with prevout height and mtp and spender height metadata, allowing the tx to be fully validated, dos checked, and tested for confirmability, using the chain::transaction check/accept/connect/confirm methods. Since the confirmability checks for blocks are performed in the store for IBD performance optimization, this is only used for tx pool acceptance. Even though we don't yet have the pool, the code is now complete to validate txs against store, including with a tx pool in the store (as in version3) and thereby allows txs to be submitted by clients (such as electrum or bitcoind interfaces), or by peers. Though the storage and relay of txs is not implemented, it's very little remaining work, maybe one day.
I did some refactoring on the electrum (and native) endpoints, splitting them into their own files, grouped by category, as they were getting big. Got some details on the electrum interface from the network dev. Some minor tweaks required based on undocumented history. Comments added to our code for that. We'll have full support for electrum v1.0 - v1.6 (current).
https://github.com/spesmilo/electrum-protocol/issues/9#issuecomment-4188538470
evoskuil04:51
Implemented most of the four electrum payment address methods, as well as the newer "scripthash" address methods that replace them. These are implemented using the same asynchronous technique developed for the native interface, since these queries are arbitrarily large. These are:
1 cancellable
2 cancel when the channel closes
3 use the same parallelizable store methods as native
4 parallelize when
database.turbo is configured (no parameter option)
The four legacy methods (using p2pkh and p2sh addresses as keys) are identical to the newer scripthash-based methods after address conversion (the sha256 hash of the output script is derivable from p2pkh/p2sh addresses). So the four older methods and newer methods each perform their own version validations and then just pass into common code for the bulk of the implementation.It's mostly cut and paste and some minor store work at this point, and those 8 methods will be complete. Maybe another day to complete the address (and corresponding new scripthash) subscription/notification/subscription (about half done now). After that just need to hook up the fee estimator to one electrum method and the interface is complete.
evoskuil19:06
Answered my own question, lolz. Though it looks like they don't actually perform this comparison - using status only as a change indicator.
(edited)evoskuil19:16
Nope, found the implementation. So gotta compute this monster on each individual address notification.
🤓 1
evoskuil19:31
There is a single address with 5,179,482 outputs. Imagine hashing each tx hash of each of these outputs together just to provide a notification that there is a new output or spend to the address.
evoskuil20:03
It will require that the subscription performs the costly computation against block state. This requires sorting all unique parent txs of all confirmed inputs/outputs hitting an address by their height and order within the block, and combining all of those tx hashes into a sha256 midstate. Because this becomes stateful, cumulative, and not reversible, a reorg impacting the address requires it to be rebuilt. The midstate for each subscribed address can then be updated with confirmations.
Since a different sort is used for unconfirmed txs, these cannot be accumulated and must instead be recalculated in full for each notification. Since tx pooling would not result in additional indexation of the same spend upon confirmation, and thus address index is not indexed by confirmation status, this implies independent tracking of pooled txs impacting a subscribed address, so that the this status field can be computed (hash combined with the confirmed midstate)
6. Next, with mempool transactions in the specified order, append a similar string.
The only mempool consistency requirement is that we provide the same transactions upon request as have been hashed into the status.
4. For mempool transactions, we define height to be-1if the transaction has at least one unconfirmed input, and0if all inputs are confirmed. 5. Order mempool transactions by(-height, tx_hash), that is,0height txs come before-1height txs, and secondarily the txid (endianness same as human-readable hex string used for display) is used to arrive at a canonical ordering.
So there's that as well. For reasonable numbers of spends for a given address (like 1000), just performing the full computation on each notification isn't so bad. And I suspect that Electrum servers don't actually support large address notifications.
But it's not worth doing if it's going to be broken. The above non-pool implementation is simple enough, and the performance hit for large addresses will only be encountered by the initial subscription (and notification following address reorg) - similar in cost to a full history or balance query.
Adding the pool behavior will require either accumulating unconfirmed tx surrogate keys in each address subscription map, or querying for it dynamically against the unconfirmed tx metadata graph. There's no requirement to pull up old unconfirmed txs that have been stored, just as with the graph. We can pull them up at graph init if we want, but ignoring them causes no harm.
Tuesday, April 7, 2026
evoskuil06:35
I managed to complete the 8 electrum non-subscription address methods, including their rpc serialization, complex sorting, and cancellable/asynchronous behavior. Just have to write the four corresponding database queries, which are similar to the existing native queries, and then test the 8 methods, 4 queries, and 3 sorts. That'll take another day.
Then it's on to the address/scripthash (basically the same) subscription/notification. I did get some work done on the address "status" optimization. I set up a copyable midstate struct that allows incremental forward updates to the confirmed aspect of the status hash. This is a stack allocated 208 bytes that can be held in the channel with each corresponding address subscription. So if you subscribe to an address with 5 million txs, we only compute that once and then just add new spend/receive txs to the hash as they occur.
This might seem uncommon, but I was clicking randomly through the block explorer today and hit an address with 750,000 transactions. Chrome can't handle that amount of json, so we have to process address output enumerations differently, like by using the data or text accept type.
(edited)Thursday, April 9, 2026
Huddle with pmienk, eynhaender, Marnix · 36 min15:55
Monday, April 13, 2026
pmienk09:41
installation, build, cmake presets generation, ci generation have been updated. next up will be a release workflow for libbitcoin-server
👍 1👌🏻 1
pmienk17:31
Add --fprofile-update=atomic when --coverage - and subsequent regenerations:
https://github.com/libbitcoin/libbitcoin-build/pull/405
https://github.com/libbitcoin/libbitcoin-system/pull/1812
https://github.com/libbitcoin/libbitcoin-database/pull/763
https://github.com/libbitcoin/libbitcoin-network/pull/762
https://github.com/libbitcoin/libbitcoin-node/pull/994
https://github.com/libbitcoin/libbitcoin-server/pull/693
👍🏻 1
evoskuil20:58
2026.b.tc
Bitcoin’s development relies on funding from companies, foundations, and individual supporters across the ecosystem. The discussion focuses on the threat centralized funding could pose to open-source development, and explores how the community can support sustainable developer funding while preserving Bitcoin’s decentralized ethos.
👊 1
Tuesday, April 14, 2026
evoskuil05:01
After a quick trip to
(edited)PubKey NYC I've been back on the electrum interface for the last couple days. I had some discussion with Electrum folks and decided to drop in the major additions for their WIP on network protocol v1.7. Also spent a couple days working of some test and organizational backlog.
That's complete now, as is the database queries and endpoint implementation for the address queries (balance, history, mempool, listunspent). These are addressable via p2pkh/p2sh addresses (only) in early versions, via output script hash in current versions, and via output script in the next version. We just map all three on to output script hash.
The new outpoint method is mostly complete, and this adds a subscriber. There are also subscribers for the three address methods above. Most of the work for those is done. That and connection of the fee estimator to its method, and the electrum interface will be complete.🎉 1
pmienk22:37
https://github.com/pmienk/libbitcoin-server/actions/runs/24422637929
https://github.com/pmienk/libbitcoin-server/releases/tag/untagged-f9e4a0504b882ec244eb
Built, stripped (on linux), signed. Not sure about security for the test key though.
🔥 1
1 reply · pmienk · last Apr 14, 2026
pmienk23:27
May be 404 because it's prerelease and my repo. I get all the links working. Stripping both debug and release linux builds right now. Windows is whatever is coming out if default config.
Wednesday, April 15, 2026
evoskuil07:54
After taxes I managed to complete and test the new v1.7 outpoint method queries, so all electrum methods are implemented apart from subscribers and fee estimator.
Most are end-to-end tested in server as well. I think I'll work off the remaining server tests (address and outpoint) before completing the subscribers and hooking up the fee estimator.
(edited)evoskuil16:05
Just checking in following the above change. Full validation from genesis (without checkpoints or milestone) to
(edited)900,000 in 4.67 hrs, and to 945,188 in 5.22 hrs on maxi. Previous record to 900k was 4.80 hrs.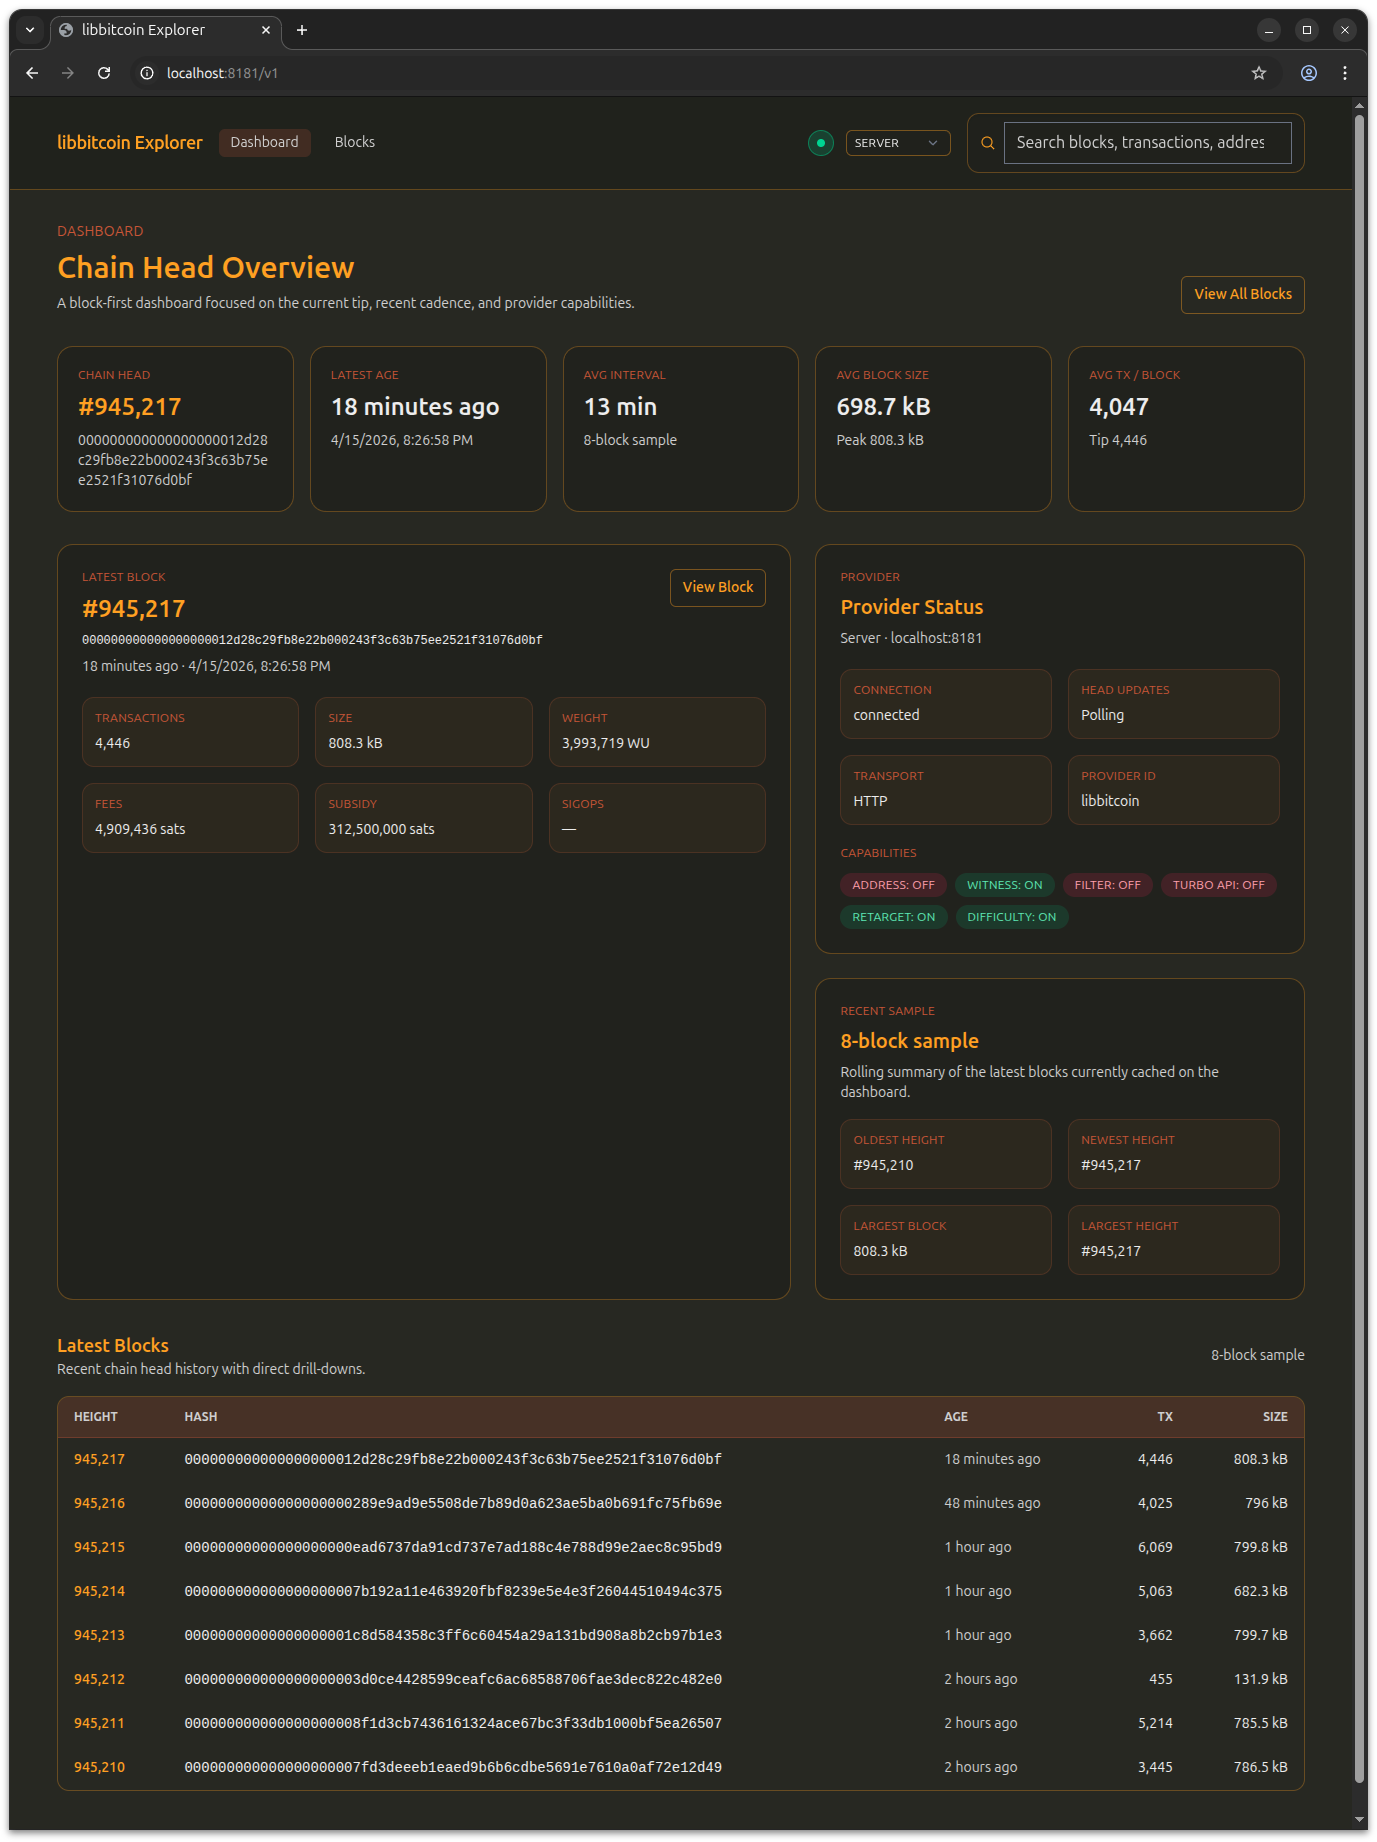

Rowan Voskuil18:49
Thanks. It dose have some issues(right now) that are cleared up in the next version. In regards to the new overhauled dashboard.
evoskuil19:05
We are at 5.8.4 and this is patched in 5.9.1, and we use these features, so yes.
(edited)evoskuil19:21
We will need a process to update wolf sources in situations like this. Do you think you could create some automation for that? I suspect the source files don't move around much, so it largely consists of mapping in all of the source files into our locations.
Thursday, April 16, 2026
evoskuil04:02
I think I'll work off the remaining server tests (address and outpoint) before...
This is now complete, ~80 test cases covering all code paths for:
blockchain.address.get_balance
blockchain.address.get_history
blockchain.address.get_mempool
blockchain.address.listunspent

blockchain.scripthash.get_balance
blockchain.scripthash.get_history
blockchain.scripthash.get_mempool
blockchain.scripthash.listunspent

blockchain.scriptpubkey.get_balance
blockchain.scriptpubkey.get_history
blockchain.scriptpubkey.get_mempool
blockchain.scriptpubkey.listunspent

blockchain.outpoint.get_status
🎉 2
Huddle with pmienk, eynhaender, evoskuil, Rowan Voskuil, Marnix · 275 min15:55
13 replies · evoskuil, eynhaender, pmienk · last Apr 16, 2026
evoskuil18:16
/// Map standard XCPU defines for intrinsics usage.
/// vc++: There are no native flags for SHA and SSE41.
#if defined(HAVE_XCPU)
    // -msha
    // vc++: SHANI not independently configurable (requires custom option).
    #if defined(__SHA__)
        #define HAVE_SHANI
        #define HAVE_SHA
    #endif
    // -mavx512bw
    // vc++: Advanced Vector Extensions 512 (X86/X64) (/arch:AVX512)
    #if defined(__AVX512BW__)
        #define HAVE_AVX512
        #define HAVE_512
    #endif
    // -mavx2
    // vc++: Advanced Vector Extensions 2 (X86/X64) (/arch:AVX2)
    #if defined(__AVX2__)
        #define HAVE_AVX2
        #define HAVE_256
    #endif
    // -msse4.1
    // vc++: Use Advanced Vector Extensions (X86/X64) (/arch:AVX).
    #if defined(__SSE4_1__)
        #define HAVE_SSE4
        #define HAVE_128
    #endif
#endif

/// Map standard ARM defines for intrinsics usage.
/// SVE maximum width is not detectable (requires custom options).
#if defined(HAVE_ARM)
    // -march=armv8-a+crypto
    // Requires 64 bit build.
    #if defined(__ARM_FEATURE_CRYPTO)
        #define HAVE_CRYPTO
        #define HAVE_SHA
    #endif
    // -march=armv8-a+sve
    // Requires 64 bit build.
    #if defined(__ARM_FEATURE_SVE)
        #define HAVE_SVE
    #endif
    // -march=armv8-a (64 bit)
    // -march=armv7-a -mfpu=neon -mfloat-abi=hard (32 bit)
    #if defined(__ARM_NEON)
        #define HAVE_NEON
        #define HAVE_128
    #endif
#endif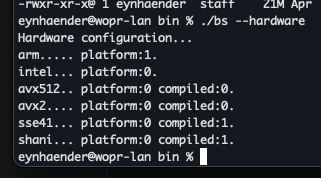
pmienk20:13
Building Mixed Arm64/x64 Applications
To build an application that utilizes x64 libraries on an Arm build, developers must use Visual Studio 2022 (version 17.3 or later) with the Arm64EC tools enabled.
The process involves configuring the project to build specific parts as Arm64EC while keeping others as standard x64, ensuring the solution links against the correct versions of dependencies.
- Configuration: In the Visual Studio Configuration Manager, create a new platform by selecting Arm64EC and copying settings from x64.
- CMake Setup: For CMake projects, add a configuration in
CMakePresets.jsonwith"architecture": { "value": "arm64ec", "strategy": "external" }and set environment variablesCXXFLAGSandCFLAGSto/arm64EC.
- Linking: When linking, use the
/machine:arm64xflag to combine the Arm64 and x64 artifacts into a single binary that can run on Arm64 devices. - Dependencies: Ensure external libraries are linked against their x64 or Arm64EC versions; if a library is only available as x64, it will run under emulation within the Arm64EC process.
evoskuil20:53
I assume the
a64 implies ARM64, and this lib doesn't exist. I'm not yet clear on where the expected path is coming from. But if I could get it to use the x64 with ARM64EC is should link.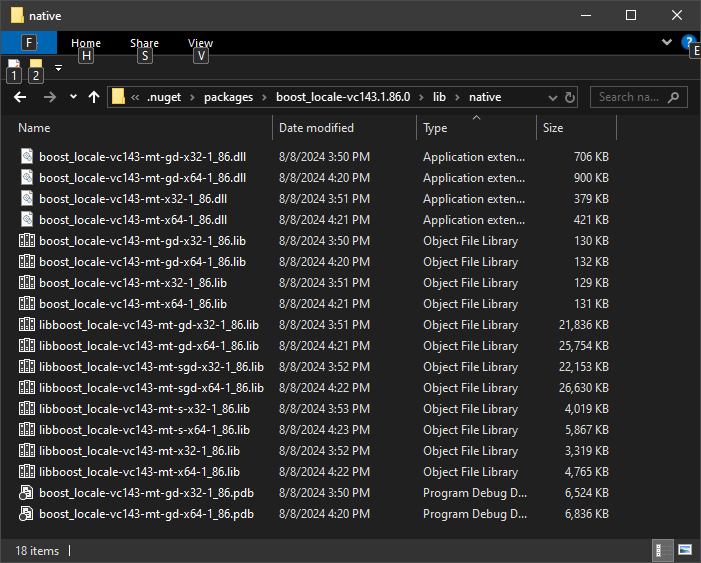
👍🏻 1
evoskuil21:14
Boost links these files based on a single header in its base header library, called
auto_link.hpp. It constructs the lib path in parts, including this:
#if defined( _M_IX86 )
#  define BOOST_LIB_ARCH_AND_MODEL_OPT "-x32"
#elif defined( _M_X64 )
#  define BOOST_LIB_ARCH_AND_MODEL_OPT "-x64"
#elif defined( _M_ARM )
#  define BOOST_LIB_ARCH_AND_MODEL_OPT "-a32"
#elif defined( _M_ARM64 )
#  define BOOST_LIB_ARCH_AND_MODEL_OPT "-a64"
#endif

...
#if defined(BOOST_LIB_NAME) \
      && defined(BOOST_LIB_PREFIX) \
      && defined(BOOST_LIB_TOOLSET) \
      && defined(BOOST_LIB_THREAD_OPT) \
      && defined(BOOST_LIB_RT_OPT) \
      && defined(BOOST_LIB_ARCH_AND_MODEL_OPT) \
      && defined(BOOST_LIB_VERSION)
So when
_M_ARM64 is defined (it is) boost switches to -a64. The issue is simply that these libs are not in the NuGet package. But good to know that boost does expect and therefore build them. I could probably copy the x64 into the expected path and link with ARM64EC.evoskuil21:16
The above is, in keeping with boost non-standardness, not consistent with NuGet targeting. For our packaging (e.g.
(edited)secp256k1) we produce the paths in the targets file (as intended), using a similar naming convention.evoskuil21:29
The copy/renaming works to get past the link errors, but then just lots of unresolved externals.
Friday, April 17, 2026
30 replies · neillm, evoskuil, pmienk · last Apr 17, 2026
evoskuil03:23
Got a couple macos green on network so I'll merge that, but my server PR will also have to clear. It may have a test failure still.
(edited)
neillm03:25
pmienk03:25
Okay... then i'll just pull get mine in as well - build scripts and such. but i've worked around this for the last six hours in some form and all other repos passed.
👍🏻 1
evoskuil03:28
The break came from a database update that server depends on. Server produced a build break before I could get it in, and that required an update to network. So that just cleared, and waiting on verification locally that server is good. 🙂
👍 1
evoskuil03:29
Neill got in before the database change, and Rowan and Phillip came in after..
(edited)😅 1
evoskuil03:30
12 years I've been fighting this. But now with more people hitting the repos again, it'll be good to mitigate it.
pmienk03:31
means we won't be exercising the install script's git clone actions for libbitcoin repos though
pmienk03:33
libbitcoin would be the 'owner', i believe that's the case with pr's as well, otherwise i'll need to spilt to two workflows. but can't confirm until test
🤔 1
evoskuil03:34
Lolz... check out the comments in the one test that's failing intermittently on macos:
    // BUGBUG: macOS:
    // Error codes have changed and the resulting race failure test is not matching expected code.
    if (!result)
    {
        BOOST_CHECK_EQUAL(ec1, error::resolve_failed);
        BOOST_CHECK_EQUAL(ec1, error::operation_canceled);
}evoskuil03:35
I'm getting an error code that's not either. I put this in there long ago so I could track it down.
evoskuil03:37
and I'm getting this...
[network:1 != ]
[network:1 != &]
of course network::1 is just
network::error::unknown, which means it's a code coming the the OS that doesn't map to anything known.waiting on network to clear
pmienk04:48
https://github.com/pmienk/libbitcoin-network/actions/runs/24548210034 - this should copy the files to downloadable artifacts if it repros and they don't print
and if it doesn't, i'll be debugging
pmienk05:10
should note, that build is against my repos as its with the other changes i'm working on so might not fail
evoskuil05:10
yeah, the one that had the failure diagnostic was in my repo. The next commit has what is probably a fix.
pmienk05:11
if you want, you can take the workflow file on that link - it adds the upload of files even without script changes
pmienk05:14
the workflow file for the run is linked: https://github.com/pmienk/libbitcoin-network/actions/runs/24548210034/workflow
The last two steps in non-msvc jobs will upload log artifacts on a failed run if they are found
anything uploaded ends up in a zip, downloadable on the workflow page
set retention to 1 day, but you can bump it if you like
My fixed build appears to have eliminated the issue, tho it's intermittent.
So here's the diagnostic build now: https://github.com/evoskuil/libbitcoin-network/actions/runs/24549071074
pmienk05:20
cool, well i'm verifying my ci changes and will execute pulls when i get confirmation past system

eynhaender06:11
The boost build on the current Visual Studio 2026 toolset is done. Packages are already published but I will need to update secp as well to be able to really test it.
🔥 1
pmienk09:32
pull requests open for CI conversion to utilize owner repositories - note that the pull requests utilize libbitcoin repositories on pull, but my private workflow used pmienk so single workflow works in both contexts.
🔥 1
Might be best to insert a make clean on successful install of a repository. Though it's the first I've encounted that
evoskuil23:33
Trying it out now, breaking change in evoskuil/node and dependent change in evoskuil/server now!
pmienk23:54
I'm far more curious to see how it resolves branch if/when something other than master is involved. it's far more likely to be problematic there
i'll probably have to add a test check, if fail fallback to master routine
Saturday, April 18, 2026
pmienk00:51
looks like they're all passing - now if you want to see the break, open both pulls at the same time and server won't have the -node copy until that pull gets accepted.
evoskuil06:21
Yeah, the approach is the same as before, but now we don't have to wait for each repo to clear.
Monday, April 20, 2026
evoskuil04:45
Just completed the implementations of Electrum address/scripthash/scriptpubkey/outpoint subscription/unsubscription/notification. Took me a full day to cleanly satisfy the various concurrency requirements, but once it was done it finally looked simple again.
The key insight was to (1) use an independent strand for notifications and updates to the notification map, (2) post subscript/unsubscribe from the main channel strand into the notification strand, and (3) post notification sends from the notification strand to the channel strand. This allows the notifications to be simply iterate in a for loop, posting into the notification strand buffer, and allows one request to run concurrently with the notification loop.
This not only protects the map during iteration and updates, and the socket during sends, but also keeps the socket active during the potentially long-running notification queries and loop. The queries are themselves cancellable, and this combination gives us immediate stop initiated by channel close and therefore also for node close.
Previously I had done something similar for long-running non-notification address queries, but that was initiated by the caller, on the socket, not a block or tx organized event originating from the node on an independent strand or even threadpool. So in that case it was necessary to post to an independent thread, establish a socket monitor (to capture socket cancellation), run the long cancellable query, and post the results back the channel strand, releasing the monitor.
But this doesn't satisfy the requirements of an independent job showing up at any time when the socket is either listening or even processing a request, and when the channel strand may be attempting to modify the subscription map. It was getting ugly, and this made it simple again. One strand for incoming callers, and one strand for outgoing notifications, and both bounding to/from the other like magic. :)
evoskuil04:52
A nice benefit of this approach was that that notification map does not have to be copied and doesn't require any guards to be safely iterated, despite callers attempting to update it. Copy-free, lock-free, and the socket remains active. The one case where the caller will get blocked is when we are processing a notification and the caller is attempting to make a subscription or desubscription. In this case the channel strand posts to the notification strand and while the notifications are being process, the update job just sits in the queue. Once the notifications clear and the update job executes, its completion handler reestablishes the socket listener. But this is exactly what we want to happen. We are busy responding to the caller with notifications from a new event, and the caller is waiting to complete his new subscription/desubscription only during that time. And of course the channels are entirely independent of each other, so everything keeps moving. The server remains fully protected against DoS, as the callers do not control the rate or volume of notifications.
(edited)evoskuil05:02
Tomorrow is a significant optimization between the server and database in terms of computing electrum address status (ordered hash of all address history). I've implemented midstate hash caching maintained in each subscription at the server protocol object, with an address table surrogate key for the head of the last iteration applied to the midstate. The hash preimage requires an ordering of all txs creating and spending a given address. There are addresses with 5 million spends, possibly as much as 10 million history entries. Without this caching, just subscribing to an address requires the full query to run for every new block and even every new unconfirmed tx. This is because the notification for any new touch on the address requires the FULL SET of touches to be hashed in order. The ordering is such that a new event can cause a change in the middle of the hash preimage. So even midstate caching gets complex. Yes, this is a crazy design.
(edited)🫣 1
evoskuil05:26
So the approach is to rely on the relative stability of confirmed history, and recompute unconfirmed history on each even. Fortunately the sort places confirmed history first in the preimage. The simple approach is to wipe the midstate cache whenever there is a reorganization (confirmed block height reduced), because the midstate cannot be rolled back.
The address hash table is a multimap, which allows iteration from the bucket to the end of the conflict list (though the iterator skips over conflicts and only exposes matches). So it presents as a stack, with the most recent item at the top (in the hashmap bucket). So we store the top at the start of the iteration, grab all of the entries and spenders, sort by confirmed state, and hash the confirmed ones using the streaming hash accumulator. Once the last confirmed is committed to the accumulator, we save off the accumulator to the subscription, and continue with the unconfirmed.
The set of unconfirmed can change completely given just one new tx in the mix, so there is no benefit in caching. But the number of them is generally trivial by comparison. For the 5M output address there may be zero or one touch unconfirmed. Still, we need to find all of them, and they can be any depth in the stack for a given address. So on the first iteration, we read the entire set. On subsequent iterations, we set the iterator to stop at the previous top, and we read for confirmed entries only. We sort and hash these into the midstate, update the cache, and then read the entire stack for unconfirmed entries. Since this will be updating with each block (at least) the confirmed query will be trivial and require almost no hashing.
The unconfirmed iteration ignores all entries for which the associated tx is not associated to a block (not strong). However it still hits every single element in the conflict list (e.g. 5M). But the cost of this query is dramatically reduced because there are a trivial number of unconfirmed, and new entries require a fee computation prevout confirmedness, and position/height. So basically, by caching the midstate, we still have to run a long iteration, find each tx instance, and check each for confirmation, but overall the query cost is cut dramatically, and the hash cost is eliminated almost entirely.
(edited)So for the crazy addresses, it will still be slowish on updates, maybe 10 second for the initial scan and 1 second for updates. But it won't be prohibitive. And these queries are set up to allow our turbo config option to run then on all CPUs.
This is by far the nuttiest query requirement I've seen yet.
evoskuil05:36
The performance fallback option is to just put a limit on the size of an address that can be subscribed. Because each update essentially requires a cumulative scan of the entire update history, that ultimately becomes necessary. So once the subscription scan hits a certain depth it just errors out and fails the subscription with a specific code. This would be a reasonable precaution for public servers. And since these queries operate over a collection of output links that are accumulated up-front, this is very simple and inexpensive to evaluate.
(edited)@John Doe has joined the channel21:29
Tuesday, April 21, 2026
@Eric Lombrozo has joined the channel03:07
@spammer (deactivated) has joined the channel10:34

2 replies · Enligths, pmienk · last Apr 21, 2026
Wednesday, April 22, 2026
evoskuil01:45
Ok, all of that stuff above is done, and tested at the database. A few hours of testing tonight at the server subscription/notification endpoints for address/scripthash/scriptpubkey and outpoint will wrap it up. I'll sync up a store with address index tonight and tomorrow we'll have a looksee at the performance benefit of the midstate hash optimization. The last remaining non-mempool item on Electrum is then hooking up the fee estimator.
👌🏻 1👌 2
evoskuil02:01
It was pretty trivial to update the client/server functional test harness to emit a notification (e.g. new block or tx), which is the notification trigger for subscriptions. The test socket just does the handshake, the subscription, calls notify, reads the socket. Super simple right in the boost test cases. Between calls blocks and/or txs can be added and/or confirmed.
(edited)evoskuil17:20
Milestone run with
full address index (all outputs by script hash) in 1.14 hrs on maxi.IOW the incremental sync time cost of syncing up ElectrumX server is 10 minutes over the < 1 hour node sync time.
(edited)Total store size with full address index to block
(edited)946,213 (current) is 1,059,591,596,235 bytes (986GB).Thursday, April 23, 2026
Any lurkers who will be in Vegas on Apr 26-29 feel free to contact me. We have a house, with a pool, and will be having our first f2f team meeting in over 10 years!
🙌 1🎉 1🔥 1
1 reply · neillm · last Apr 23, 2026
evoskuil04:34
And someone with actual skilz maybe make a better promo image, with like the actual logo, and dates, and a proper Vegas cityscape... and I'll post it to twitter.
3 replies · neillm, evoskuil · last Apr 23, 2026
evoskuil08:34
Working through unit testing for the subscribers and found a design flaw in the status accumulation optimization. Hopefully will have that resolved and tested tomorrow.
Huddle with pmienk, eynhaender, evoskuil, Rowan Voskuil, Marnix · 160 min15:46
1 reply · evoskuil · last Apr 23, 2026
evoskuil16:54
libbitcoin-server:     4.0.0
libbitcoin-node:       4.0.0
libbitcoin-network:    4.0.0
libbitcoin-database:   4.0.0
libbitcoin-system:     4.0.0
1 reply · neillm · last Apr 24, 2026
neillm01:26
I'm close to a keto diet, but not exactly as strict. I generally avoid sugar and carbs these days
Friday, April 24, 2026
evoskuil04:08
Above mentioned design flaw is resolved, using height-based vs. able-based cursor, and retaining the midstate caching optimization. This is also more efficient than the initial attempt. Address/scripthash/scriptpubkey subscriptions are all succeeded, including idempotent subscribe and progressive subscribe after history changes with incremental status accumulation.
Also the first notification (server-initiated message) is now integrated into the unit tests, with the unit test sending a node event, causing server subscriptions to evaluate and send as applicable, and then receiving the json-rpc notification. Triggering the notify at the server is just:
notify(node::chase::organized, {}); and handling it is just: const auto message = receive(); where the message is the json-rpc notification from the server.evoskuil04:43
So all subscription, notification, and unsubscription is now implemented. The only major open item on electrum is integration of the fee estimator.
(edited)evoskuil05:01
After all that, the fully optimized implementation is fundamentally just this method. This is running on the channel's notification strand.
stopping_ is an atomic bool that gets set via socket (or process) termination on the main channel strand, passed into the expensive query for cancellation. sub.cursor is now a height-based cursor, and r/w parameter to the query, which updates each read to the top of the chain, so most reads will only accumulate one block of confirmed related txs. The limit parameter is from config, and will terminate the query with an error if the number of address outputs exceeds that value (though it can really handle any volume). turbo_ is also config, allowing the store query to be run on all available threads (across the set of potentially millions of outputs). The hash accumulator sub.accumulator is stored with the cursor and the last status hash sub.status on the subscription (144 bytes + 32 byte scripthash key for each subscription of the channel). The accumulator is copied after the confirmed txs are appended to it, and the unconfirmed are then accumulated and flushed as the next sub.status, which is then sent as the notification if it has changed.
code protocol_electrum::get_scripthash_history(address_subscription& sub,
    const hash_digest& hash, size_t limit) NOEXCEPT
{
    BC_ASSERT(notification_strand_.running_in_this_thread());

    histories history{};
    const auto& query = archive();
    if (const auto ec = query.get_history(stopping_, sub.cursor, history,
        hash, limit, turbo_))
        return ec;

    if (history.empty())
        return error::success;

    auto it = history.cbegin();
    while (it != history.cend() && it->confirmed())
        write_status(sub.accumulator, *it++);

    midstate copy = sub.accumulator;
    while (it != history.cend())
        write_status(copy, *it++);

    sub.status = copy.flush();
    return error::success;
}
Monday, April 27, 2026
@Ovi Trif has joined the channel08:39
Tuesday, April 28, 2026
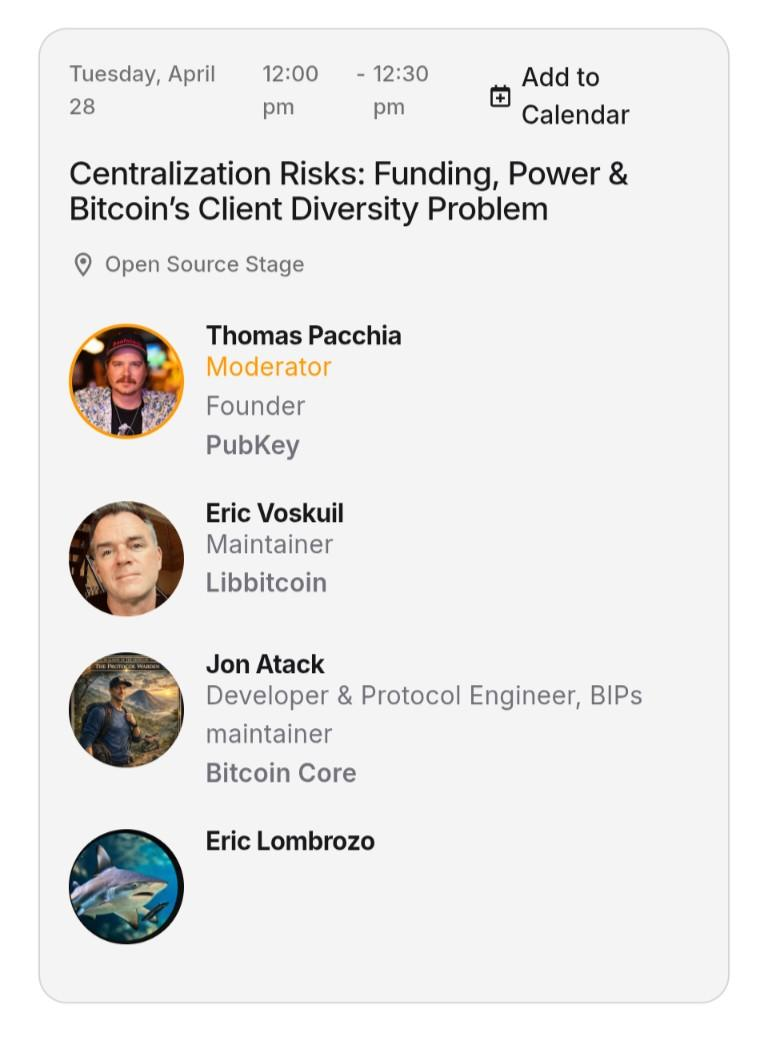
Wednesday, April 29, 2026
eynhaender04:06
freedomtechsummit.com
Freedom Tech Summit (formerly dev/hack/day) - Year 4 of the one-day conference for developers, hackers, and tech enthusiasts diving deep into Bitcoin, Lightning, Cashu, Nostr, MeshCore, and cutting-edge freedom technologies. June 10, 2026 in Prague.
Thursday, April 30, 2026
pmienk15:51
Starting meeting in 5, anyone who was in Vegas, totally understand needing to sleep. Will stick around at least an hour if later start is required. Shout out if we need to reschedule.
Huddle with pmienk, neillm, evoskuil, eynhaender, Rowan Voskuil · 106 min15:55
4 replies · neillm, evoskuil · last Apr 30, 2026
pmienk15:56
I can't either, and I'm getting a 'We are not detecting any audio from your microfphone error
evoskuil23:26
I've implemented the workaround for Electrum json-rpc non-compliance (singleton params in two methods, one request and one response), PRs running now.
evoskuil23:48
I've implemented the temporary resolution to the electrum client testing but defaulting
(edited)estimate_fee and get_fee_histogram, added to server PR.