
Bitcoin full node and query server
January 2025
Archive of the libbitcoin Slack #general channel.
Wednesday, January 1, 2025

evoskuil19:47
After spending a good amount of time on a utxo accumulator in an attempt to parallelize confirmations, I've come to the conclusion that this is not really possible. The accumulation must be performed sequentially to be useful, even if it's performed in parallel by block and then rolled up - the roll up is at best log(n) by splitting sets of blocks into halves and rolling up. But each division increases the cost of the roll-up accordingly, so it amounts to the same. It's still linear in the chain to accumulate the outputs. And the accumulation is only useful at its current height, requiring all previous blocks accumulated.
So if you have a milestone/checkpoint segment, you need to roll all of that up as well. That can take as long as the sync itself, or longer, just to obtain the previous outputs. I tested this by just querying to obtain the inputs and their previous outputs by
uint64_t primary key (not hash IDs). Just querying to obtain all of these takes almost 2 hours on a machine where the sync take 50 minutes. The big part of this cost is associating the prevouts, since they are pointed to by the inputs points, which are natural keys [hash:index]. This is necessary due (1) download concurrency, and (2) write-only tables - which are why the sync is fast.
We pay this cost once already, during validation, to obtain the prevouts for validation. Any implementation needs to do this - to search for the hashes to match up inputs to prevouts. But to perform confirmation we are doing it a second time (for the blocks that are not checkpoint/milestone, the ones we validate). So the idea of accumulation was that we could accumulate in the same (validation) stage, and roll up out of order. However that requires significant additional work for milestone/checkpoint runs in order to fully populate the accumulator. It also then requires total ordering, as described above...evoskuil19:57
So I decided that our method of confirming only blocks that we are validating is probably optimal, yet we need a way to reduce this prevout association cost. This is a hashmap search of each input point (32 byte hash), and a hashmap search of each of these hashes in the tx table, in order to obtain a link to the puts table entry which provides the list of outputs. The links are very fast, but big table hashmap searches are much more expensive, and we avoid them during sync to prevent thrashing.
To put it in context, there are 1.03 billion entries in the tx table, and 2.6 billion entries in the input point table (unless compressed but that requires search during sync). This means that we are searching through the entire 2.6 billion entry table and 1.03 billion entry table, 2.6 billion times each. That's 5.2 billion hashmap searches performed during validation, and again during confirmation, if we are validating/confirming the full chain. That's
(edited)10.4 billion hashmap searches just to associate all of the previous outputs. It's very fast considering, but can be much better.evoskuil21:56
The big machine (no shani) completes a full sync, validation, and confirmation in 5.4 hours. That's with all
10.4 billion prevout searches (there are a lot more queries, but I'm focused on these specifically). Validate only (no download, no confirm) takes 3.4 hours. So 2 hours is consumed in download and confirm (where download alone takes 50 minutes). This time compresses when each runs concurrently, given enough RAM. So I'm working to get this down to about 4.5 hours in the big machine by optimizing confirmation.evoskuil22:58
So I'm planning to use some disk space for optimization of this expensive navigation. During validation, when validated prevouts are necessarily navigated, we can obtain the full set of output primary keys in order, for the given block.
We can then store these in an array table contiguously (5 bytes each). The offset to the start of this set is an array index in the table, which is also 5 bytes, since there's one element for each of 2.6 billion inputs (ceiling(log2(2.8b)) = 32 and one more byte is required for growth). This implies a main table of 12.2GiB to hold the prevout primary keys in groups by block.
Since blocks are validated out of order, which is where we obtain this set, we write the set in the validation chaser. The sets are written out of order and require an ordered index. We don't want to be searching for them, as that's the original problem. So we don't simply append to a hash table using the block primary key. Instead we bend one of our rules and then compensate for it.
The prevout table is an array with a trivial (empty) head. We then provide a small array index, very much like the candidate and confirmed indexes, where the entry in the index is the prevout table PK for the block, and the array offset of the index is the candidate block height. This provides direct navigation from the block height to the set of prevout (output) primary keys. From this there is also direct navigation to the tx and direct access to the output index, value, and script. We can then search the tx PK in the strong_tx table for ordered confirmedness.
However we also need to know which of the outputs are of the coinbase. These will always be first, but the count must be known, since a CB can have any number of outputs. Instead of marking every one of billions of entries with a 1 byte boolean (2.4GiB) we add the a byte count to the index entry (2.4 MiB). We could also merge a 1 bit flag into every output PK, which would be free apart from trivial processing.
But we also need the height and mtp of the prevout.tx.header (prevout's block) so that we can perform maturity checks (coinbase maturity and bip68 relative locktime). We could possibly perform these during validation, though that requires some denormalization, since these take a dependency on the prevout's tx/block, which are not referenced in validation. This can be resolved by storing the header PK (3 bytes) with the prevout PK. This bumps us up from 12.2GiB to 19.4GiB, so not trivial. This could be optimized out by the denormalization. Also the coinbase outputs can be derived from the block's first tx, but that's more costly than saving the bits is worth. The minimum cost for the scheme is about 12.2GiB.
evoskuil23:39
So we start with the normal form at 19.4GiB and optimize down to 12.2GiB, and have search-free access to all prevouts and required metadata for confirmation.
For every block we validate, we confirm that each prevout is in a candidate block by chasing the prevout.tx->strong_tx. If the strong_tx is not found there is a possibility of a duplicate tx having been stored, one for the strong candidate block and one discovered in the validation search. In this case the full set of txs with that hash much be search. This is extremely rare but must be covered (never happens in pure uninterrupted block sync/validation but may happen with unconfirmed txs, reorganizations, or disk full stops).
evoskuil23:51
This covers the question of spendability (strong, mature, unlocked prevout). The other question is spentness. Spentness must search for any *other* confirmed input that spends the input's prevout. So this is not a search over prevouts (outputs) but a search over inputs (two inputs with the same spend target).
(edited)Thursday, January 2, 2025
evoskuil08:15
The bending of the rules pertains to append-only table bodies. There is already a slight bend to this in the case of the two height indexes (simple arrays), as we allow the arrays to shrink during a reorg, and then grow again. In the case of a new prevouts table, the index table for the prevouts (also a simple array) must be written out of order. The height indexes are pure stacks (push/pop only). The block order is dictated by the order of block validation. This technique allows the node to produce a sort of the unsorted validation order at no cost - by just inserting the prevouts reference into the table at the height offset.
evoskuil08:24
This will leave array gaps for blocks not to be validated, and for blocks pending validation. If there is a stop with the pending validation gaps, a restart at a restore point will cause the gapped blocks to be validated with prevouts filled in to the table and its index. But the snapshot cannot be relied upon in the range where writes have occurred since the last snapshot (guaranteed flush). This is essentially the same problem as with the height indexes. These can be managed in the backup and restore process due to the simplicity of the tables.
Huddle with pmienk, evoskuil, Marnix, David Chocholatý, cguida, Enligths · 115 min20:57
Friday, January 3, 2025
evoskuil07:46
I was able to simplify this confirmation caching design a lot. The tx locking (prevent duplicates while confirming) idea is out, too costly and complex, and not necessary. By merging the point table back into the spend table things also get simpler, and we save 19GB on the current store and drop a table. The only downsides are we can't optionally reduce store size by 50GB through point hash consolidation, but it's a little costly during sync, and prohibitive on small machines. Hopefully the significantly increased size of the spend table wouldn't create a new paging issue, but I don't think so. It's less data and fewer queries overall. In that consolidation we drop a 4 byte link and 4 byte reference for every spend, so we save 19GB total, which incidentally is the same size of the new cache. However the new cache can be dropped after validation. So this saves us an actual 19GB over the uncompressed store state, at the cost of not being able to compress out another 31GB. That puts us very close to Core store size (we were 25 GB larger or smaller depending on the consolidation option).
The cache itself becomes the id of the prevout tx (4 bytes) and the id of the spend of the prevout (4 bytes). With these two values there are no hashmap searches apart from searching for the confirming (strong) block of the tx. Basically everything is done in validation, which is parallel by block, except for this last step, which cannot be parallelized because the strong relation must be done in order by block while confirming. So I feel pretty good about the optimization being right at this point, and that it will be very effective.
evoskuil07:53
There is still the caveat that if we don't find the prevout.tx in a strong state we need to look for duplicates, but this is simple/free and preserves our loose coupling. The possibility of duplicate txs affecting strong double spends just requires that we enumerate them all (iterator walk thru spend table). But the table consolidation above reduces that significantly by removing a multiple of iterations (basically all outputs of a tx vs. the one we are looking for), and cuts the number of hashmap searches in half for this aspect, since both point and spend table were being searched. So it's something like 10B searches reduced to 2.5B, and other stuff. :)
The only other caveat is that I've got to manage the dynamic table body for the cache index table, which isn't risky or hard just feels a little hacky.
evoskuil08:02
Also note that this will slightly increase the cost of validation, by implementing the cache writes, though the lack of a hashmap header update and the fact that there is only one write per block, should make it pretty minor, maybe up to +5% validation time.
But I'll just implement the validation collection of the data buffer for the cache write first, and wee what that does, if anything. Then I'll add the tables and writes, then consolidate point/spend tables. Prob will take the week. But should be sweet.
evoskuil18:57
Ok, I think I figured out the best way to handle the random access index population for the prevout confirmation cache. It's really a table head, providing pointers into the array. Table heads are random access, which resolves the fault recovery question. The issue then moves to the fact that our table headers are fixed length. However I don't see this as an actual constraint. The headers are fully flushed and copied on snapshot. So it just becomes an issue of generalizing the table templates to handle this type of table head.
evoskuil19:16
Our existing tables consist of a head and body, where the head stores the body size and an array of hashmap buckets. For non-hashmap tables (array or blob) the head is just a size. However this index is not a hashmap, so there's some generalization necessary.
hashmap heads are implemented using the array template. This is the same template used for array bodies. Each bucket is an offset pointer into the body, identifying the first element of the hashmap conflict list. We can generalize this array-indexed array as a hashmap with no conflicts. That requires that each valid search key has exactly one bucket. This is easy since the search key is the block height. So 850k buckets have 850k pointers into the body, and there is never a need to walk to a second element in the conflict list.
The hash function for this would be a pass-through (no-hash) of the block height. This is also something we already do, with the exception that the hash is key modulo bucket count. But in this case we don't want to modulo, we want to increase the bucket count. Bucket count is a runtime (non-template) parameter. It's defined in config and verified at startup against head size. But since it's not a template argument it's an easy change.
On verify we allow an increase (decrease still implies a fault) by just updating the bucket count member. This makes the verification a little weaker, since it trusts the increased size, but it's already weak. The check is more of a smoke check, not a true guard. So that's the first change.
On write we allow expansion of the head. Heads and bodies are implemented over the same basic mmap wrapper, which we use for this type of expansion in the bodies. However since it never happens in the heads (until now) the remap shared pointer is not necessary, as there is no reason to block global access during a remap. So in this case the remap guards must be in place, especially since writes will be concurrent (coming from the validation stage) as will reads (coming non-concurrently but concurrent with writes). So that's the second change.
When we remap we always over allocate, because remap is expensive. Heads are small, and this is with small growth, but still do not want to grow as slow as one word at a time (default behavior would be more random than that due to out of order writes at different heights). So we will have to truncate to logical size on close, which we also do for bodies but may not for heads - not sure. So that's a third thing.
snapshot/restore/disk-full are not affected. start/stop are not affected.
(edited)evoskuil19:24
The treatment of it as a specialized hashmap has one more implication. The link size (in this case 3 bytes due to the number of elements we need to index - block height) is used in the as the bucket element size, and also the single word logical body size stored in the header. In the templates this is also used for the conflict linked list pointers. That would result in each array element having an extra three bytes to hold an unnecessary null pointer. So there is an issue here where we need zero length links and 3 byte keys. I believe these are the same templatized size/type. That might be enough to cause it to become an array-indexed array, as opposed to a full hashmap. This is the fourth thing, and first to verify.
That's it, just some implementation details for a single table. The table is a cache (disposable validation data), not archive (primary data). I think I'd name it
(edited)prevout.M
Marnix19:31
on a fresh install on debian 12, bn was working.
Then I executed ./bn -t
./bn -t
Using default configuration settings.
Database is started.
Getting first [100] output address hashes.
Segmentation fault
and now bn doesn't run anymore
./bn
2025-01-03T16:18:31Z.0 ====================== startup =======================
2025-01-03T16:18:31Z.0 Using default configuration settings.
2025-01-03T16:18:31Z.0 Database failed to start with error 'flush lock failure'.
2025-01-03T16:18:31Z.0 Please wait while restoring from most recent snapshot...
2025-01-03T16:18:31Z.0 restore::recover_snapshot(store)
2025-01-03T16:18:31Z.0 Database restore failed with error 'missing snapshot'.
2025-01-03T16:18:31Z.0 Node stopped successfully.
2025-01-03T16:18:31Z.0 ====================== shutdown ======================
2025-01-03T16:18:31Z.0 Press <enter> to exit...
how to fix?
121 replies · evoskuil, Marnix, cguida · last Jan 06, 2025
evoskuil19:35
I don't know what the issue with the test query was, but it's a fairly lengthy ad-hoc piece of temporary code, so not surprising.
evoskuil19:36
Running it at the console, for the current query, causes a massive dump to the console, but that should be ok. I'll look at it and see if there's anything obvious.
evoskuil19:38
The error occurred between these two console writes:
void executor::read_test(bool dump) const
{
    using namespace database;
    constexpr auto start_tx = 1'000'000_u32;
    constexpr auto target_count = 100_size;

    // Set ensures unique addresses.
    std::set<hash_digest> keys{};
    auto tx = start_tx;

    logger(format("Getting first [%1%] output address hashes.") % target_count);

    auto start = fine_clock::now();
    while (!cancel_ && keys.size() < target_count)
    {
        const auto outputs = query_.get_outputs(tx++);
        if (outputs->empty())
        {
            // fault, tx with no outputs.
            return;
        }

        for (const auto& put: *outputs)
        {
            keys.emplace(put->script().hash());
            if (cancel_ || keys.size() == target_count)
                break;
        }
    }

    auto span = duration_cast<milliseconds>(fine_clock::now() - start);
    logger(format("Got first [%1%] unique addresses above tx [%2%] in [%3%] ms.") %
keys.size() % start_tx % span.count());evoskuil19:44
The query just arbitrarily starts collecting outputs at the 1 millionth tx in the store (by insertion order (primary key).
evoskuil19:47
That shouldn't cause a segfault obviously, but it hasn't been tested. But at least it may repro here.
evoskuil19:54
The tx doesn't exist. All txs that get stored have outputs, so it's generally a safe assumption. And I think in this code I assumed it would come back empty if non-exist, but it comes back null to indicate the error.
evoskuil19:55
The reason a tx that doesn't exist is getting dereferenced is this hacky test technique of just grabbing txs from the store based on a made up (not queried) primary key.
evoskuil19:58
You can pull the change to libbitcoin-node and rebuild, or just change that line to this:
        const auto outputs = query_.get_outputs(tx++);
        if (is_null(outputs))...
The test would just end normally if there is a missing tx.
M
Marnix20:03
./bn
2025-01-03T16:57:47Z.0 ====================== startup =======================
2025-01-03T16:57:47Z.0 Using default configuration settings.
2025-01-03T16:57:47Z.0 The "bitcoin" database directory does not exist.
2025-01-03T16:57:47Z.0 Using default configuration settings.
2025-01-03T16:57:47Z.0 Initializing "bitcoin" directory...
2025-01-03T16:57:47Z.0 Failed because the directory "bitcoin" already exists.
2025-01-03T16:57:47Z.0 Node stopped successfully.
2025-01-03T16:57:47Z.0 ====================== shutdown ======================
2025-01-03T16:57:47Z.0 Press <enter> to exit...
bitcoin dir doesn't exist -> initializing bitcoin dir -> fail because bitcoin dir already exists🤔
evoskuil20:07
The check for existence returned false, and the attempt to create failed because it already existed. Not sure how that happens on Linux, seems like a race. Was the directory fully deleted?
M
Marnix20:09
yes, earlier I encountered this btw
"bus error"
./bn -n
Using default configuration settings.
Initializing "bitcoin" directory...
Please wait while creating the database...
create::create_file(header_head)
create::create_file(header_body)
create::create_file(input_head)
create::create_file(input_body)
create::create_file(output_head)
create::create_file(output_body)
create::create_file(point_head)
create::create_file(point_body)
create::create_file(puts_head)
create::create_file(puts_body)
create::create_file(spend_head)
create::create_file(spend_body)
create::create_file(tx_head)
create::create_file(tx_body)
create::create_file(txs_head)
create::create_file(txs_body)
create::create_file(candidate_head)
create::create_file(candidate_body)
create::create_file(confirmed_head)
create::create_file(confirmed_body)
create::create_file(strong_tx_head)
create::create_file(strong_tx_body)
create::create_file(validated_bk_head)
create::create_file(validated_bk_body)
create::create_file(validated_tx_head)
create::create_file(validated_tx_body)
create::create_file(address_head)
create::create_file(address_body)
create::create_file(neutrino_head)
create::create_file(neutrino_body)
create::open_file(header_head)
create::open_file(header_body)
create::open_file(input_head)
create::open_file(input_body)
create::open_file(output_head)
create::open_file(output_body)
create::open_file(point_head)
create::open_file(point_body)
create::open_file(puts_head)
create::open_file(puts_body)
create::open_file(spend_head)
create::open_file(spend_body)
create::open_file(tx_head)
create::open_file(tx_body)
create::open_file(txs_head)
create::open_file(txs_body)
create::open_file(candidate_head)
create::open_file(candidate_body)
create::open_file(confirmed_head)
create::open_file(confirmed_body)
create::open_file(strong_tx_head)
create::open_file(strong_tx_body)
create::open_file(validated_bk_head)
create::open_file(validated_bk_body)
create::open_file(validated_tx_head)
create::open_file(validated_tx_body)
create::open_file(address_head)
create::open_file(address_body)
create::open_file(neutrino_head)
create::open_file(neutrino_body)
create::load_file(header_head)
create::load_file(header_body)
create::load_file(input_head)
create::load_file(input_body)
create::load_file(output_head)
create::load_file(output_body)
create::load_file(point_head)
create::load_file(point_body)
create::load_file(puts_head)
create::load_file(puts_body)
create::load_file(spend_head)
create::load_file(spend_body)
create::load_file(tx_head)
create::load_file(tx_body)
create::load_file(txs_head)
create::load_file(txs_body)
create::load_file(candidate_head)
create::load_file(candidate_body)
create::load_file(confirmed_head)
create::load_file(confirmed_body)
create::load_file(strong_tx_head)
create::load_file(strong_tx_body)
create::load_file(validated_bk_head)
create::load_file(validated_bk_body)
create::load_file(validated_tx_head)
create::load_file(validated_tx_body)
create::load_file(address_head)
create::load_file(address_body)
create::load_file(neutrino_head)
create::load_file(neutrino_body)
create::create_table(header_table)
create::create_table(input_table)
create::create_table(output_table)
create::create_table(point_table)
create::create_table(puts_table)
create::create_table(spend_table)
create::create_table(tx_table)
Bus error
evoskuil20:11
Another cause of bus errors (on Linux anyway) is when the operating system can't back a virtual page with physical memory (e.g. low-memory conditions or out of huge pages when using huge page memory.)
evoskuil20:13
Those table creations will allocate 1/4 the size of the chain. So about 150GB of memory map. I've done very little v4 testing on Linux, but v3 uses basically the same techniques.
(edited)M
Marnix20:19
It failed once and then it worked another time?
after that it keeps saying the bitcoin dir already exists, but it doesn't 🤷♂️
evoskuil20:24
Return value
true if a directory was newly created for the directory p resolves to, false otherwise.
evoskuil20:48
I added the full error message to the output:
Initializing "M:/bitcoin/" directory...
Failed creating directory "M:/bitcoin/" with error 'is a directory'.
evoskuil20:49
M
Marnix20:05
fresh install, execute install script, run bn:
./bn
2025-01-05T16:58:12Z.0 ====================== startup =======================
2025-01-05T16:58:12Z.0 Using default configuration settings.
2025-01-05T16:58:12Z.0 The "bitcoin" database directory does not exist.
2025-01-05T16:58:12Z.0 Using default configuration settings.
2025-01-05T16:58:12Z.0 Initializing "bitcoin" directory...
2025-01-05T16:58:12Z.0 Please wait while creating the database...
2025-01-05T16:58:12Z.0 create::create_file(header_head)
2025-01-05T16:58:12Z.0 create::create_file(header_body)
2025-01-05T16:58:12Z.0 create::create_file(input_head)
2025-01-05T16:58:12Z.0 create::create_file(input_body)
2025-01-05T16:58:12Z.0 create::create_file(output_head)
2025-01-05T16:58:12Z.0 create::create_file(output_body)
2025-01-05T16:58:12Z.0 create::create_file(point_head)
2025-01-05T16:58:12Z.0 create::create_file(point_body)
2025-01-05T16:58:12Z.0 create::create_file(puts_head)
2025-01-05T16:58:12Z.0 create::create_file(puts_body)
2025-01-05T16:58:12Z.0 create::create_file(spend_head)
2025-01-05T16:58:12Z.0 create::create_file(spend_body)
2025-01-05T16:58:12Z.0 create::create_file(tx_head)
2025-01-05T16:58:12Z.0 create::create_file(tx_body)
2025-01-05T16:58:12Z.0 create::create_file(txs_head)
2025-01-05T16:58:12Z.0 create::create_file(txs_body)
2025-01-05T16:58:12Z.0 create::create_file(candidate_head)
2025-01-05T16:58:12Z.0 create::create_file(candidate_body)
2025-01-05T16:58:12Z.0 create::create_file(confirmed_head)
2025-01-05T16:58:12Z.0 create::create_file(confirmed_body)
2025-01-05T16:58:12Z.0 create::create_file(strong_tx_head)
2025-01-05T16:58:12Z.0 create::create_file(strong_tx_body)
2025-01-05T16:58:12Z.0 create::create_file(validated_bk_head)
2025-01-05T16:58:12Z.0 create::create_file(validated_bk_body)
2025-01-05T16:58:12Z.0 create::create_file(validated_tx_head)
2025-01-05T16:58:12Z.0 create::create_file(validated_tx_body)
2025-01-05T16:58:12Z.0 create::create_file(address_head)
2025-01-05T16:58:12Z.0 create::create_file(address_body)
2025-01-05T16:58:12Z.0 create::create_file(neutrino_head)
2025-01-05T16:58:12Z.0 create::create_file(neutrino_body)
2025-01-05T16:58:12Z.0 create::open_file(header_head)
2025-01-05T16:58:12Z.0 create::open_file(header_body)
2025-01-05T16:58:12Z.0 create::open_file(input_head)
2025-01-05T16:58:12Z.0 create::open_file(input_body)
2025-01-05T16:58:12Z.0 create::open_file(output_head)
2025-01-05T16:58:12Z.0 create::open_file(output_body)
2025-01-05T16:58:12Z.0 create::open_file(point_head)
2025-01-05T16:58:12Z.0 create::open_file(point_body)
2025-01-05T16:58:12Z.0 create::open_file(puts_head)
2025-01-05T16:58:12Z.0 create::open_file(puts_body)
2025-01-05T16:58:12Z.0 create::open_file(spend_head)
2025-01-05T16:58:12Z.0 create::open_file(spend_body)
2025-01-05T16:58:12Z.0 create::open_file(tx_head)
2025-01-05T16:58:12Z.0 create::open_file(tx_body)
2025-01-05T16:58:12Z.0 create::open_file(txs_head)
2025-01-05T16:58:12Z.0 create::open_file(txs_body)
2025-01-05T16:58:12Z.0 create::open_file(candidate_head)
2025-01-05T16:58:12Z.0 create::open_file(candidate_body)
2025-01-05T16:58:12Z.0 create::open_file(confirmed_head)
2025-01-05T16:58:12Z.0 create::open_file(confirmed_body)
2025-01-05T16:58:12Z.0 create::open_file(strong_tx_head)
2025-01-05T16:58:12Z.0 create::open_file(strong_tx_body)
2025-01-05T16:58:12Z.0 create::open_file(validated_bk_head)
2025-01-05T16:58:12Z.0 create::open_file(validated_bk_body)
2025-01-05T16:58:12Z.0 create::open_file(validated_tx_head)
2025-01-05T16:58:12Z.0 create::open_file(validated_tx_body)
2025-01-05T16:58:12Z.0 create::open_file(address_head)
2025-01-05T16:58:12Z.0 create::open_file(address_body)
2025-01-05T16:58:12Z.0 create::open_file(neutrino_head)
2025-01-05T16:58:12Z.0 create::open_file(neutrino_body)
2025-01-05T16:58:12Z.0 create::load_file(header_head)
2025-01-05T16:58:12Z.0 create::load_file(header_body)
2025-01-05T16:58:12Z.0 create::load_file(input_head)
2025-01-05T16:58:12Z.0 create::load_file(input_body)
2025-01-05T16:58:12Z.0 create::load_file(output_head)
2025-01-05T16:58:12Z.0 create::load_file(output_body)
2025-01-05T16:58:12Z.0 create::load_file(point_head)
2025-01-05T16:58:12Z.0 create::load_file(point_body)
2025-01-05T16:58:12Z.0 create::load_file(puts_head)
2025-01-05T16:58:12Z.0 create::load_file(puts_body)
2025-01-05T16:58:12Z.0 create::load_file(spend_head)
2025-01-05T16:58:12Z.0 create::load_file(spend_body)
2025-01-05T16:58:12Z.0 create::load_file(tx_head)
2025-01-05T16:58:12Z.0 create::load_file(tx_body)
2025-01-05T16:58:12Z.0 create::load_file(txs_head)
2025-01-05T16:58:12Z.0 create::load_file(txs_body)
2025-01-05T16:58:12Z.0 create::load_file(candidate_head)
2025-01-05T16:58:12Z.0 create::load_file(candidate_body)
2025-01-05T16:58:12Z.0 create::load_file(confirmed_head)
2025-01-05T16:58:12Z.0 create::load_file(confirmed_body)
2025-01-05T16:58:12Z.0 create::load_file(strong_tx_head)
2025-01-05T16:58:12Z.0 create::load_file(strong_tx_body)
2025-01-05T16:58:12Z.0 create::load_file(validated_bk_head)
2025-01-05T16:58:12Z.0 create::load_file(validated_bk_body)
2025-01-05T16:58:12Z.0 create::load_file(validated_tx_head)
2025-01-05T16:58:12Z.0 create::load_file(validated_tx_body)
2025-01-05T16:58:12Z.0 create::load_file(address_head)
2025-01-05T16:58:12Z.0 create::load_file(address_body)
2025-01-05T16:58:12Z.0 create::load_file(neutrino_head)
2025-01-05T16:58:12Z.0 create::load_file(neutrino_body)
2025-01-05T16:58:12Z.0 create::create_table(header_table)
2025-01-05T16:58:12Z.0 create::create_table(input_table)
2025-01-05T16:58:12Z.0 create::create_table(output_table)
2025-01-05T16:58:12Z.0 create::create_table(point_table)
2025-01-05T16:58:15Z.0 create::create_table(puts_table)
2025-01-05T16:58:15Z.0 create::create_table(spend_table)
2025-01-05T16:58:24Z.0 create::create_table(tx_table)
2025-01-05T16:58:27Z.0 create::create_table(txs_table)
2025-01-05T16:58:27Z.0 create::create_table(candidate_table)
2025-01-05T16:58:27Z.0 create::create_table(confirmed_table)
2025-01-05T16:58:27Z.0 create::create_table(strong_tx_table)
2025-01-05T16:58:31Z.0 create::create_table(validated_bk_table)
2025-01-05T16:58:31Z.0 create::create_table(validated_tx_table)
2025-01-05T16:58:35Z.0 create::create_table(address_table)
2025-01-05T16:58:35Z.0 create::create_table(neutrino_table)
2025-01-05T16:58:35Z.0 Storing genesis block.
2025-01-05T16:58:35Z.0 Created the database in 23 secs.
2025-01-05T16:58:35Z.0 Body sizes...
   header    :98
   txs       :18
   tx        :62
   point     :0
   input     :79
   output    :81
   puts      :9
   candidate :3
   confirmed :3
   spend     :24
   strong_tx :12
   valid_tx  :0
   valid_bk  :0
   address   :0
   neutrino  :0
2025-01-05T16:58:35Z.0 Table records...
   header    :1
   tx        :1
   point     :0
   candidate :1
   confirmed :1
   spend     :1
   strong_tx :1
   address   :0
2025-01-05T16:58:35Z.0 Head buckets...
   header    :524493
   txs       :524493
   tx        :551320125
   point     :546188501
   spend     :1459791875
   strong_tx :551320125
   valid_tx  :551320125
   valid_bk  :524493
   address   :1
   neutrino  :1
2025-01-05T16:58:35Z.0 Version Information...
libbitcoin-node:       4.0.0
libbitcoin-database:   4.0.0
libbitcoin-network:    4.0.0
libbitcoin-system:     4.0.0
2025-01-05T16:58:35Z.0 Hardware configuration...
2025-01-05T16:58:35Z.0 arm..... platform:0.
2025-01-05T16:58:35Z.0 intel... platform:1.
2025-01-05T16:58:35Z.0 avx512.. platform:0 compiled:0.
2025-01-05T16:58:35Z.0 avx2.... platform:1 compiled:0.
2025-01-05T16:58:35Z.0 sse41... platform:1 compiled:0.
2025-01-05T16:58:35Z.0 shani... platform:1 compiled:0.
2025-01-05T16:58:35Z.0 neon.... platform:0 compiled:0.
2025-01-05T16:58:35Z.0 Log system configuration...
2025-01-05T16:58:35Z.0 [a]pplication.. compiled:1 enabled:1.
2025-01-05T16:58:35Z.0 [n]ews......... compiled:1 enabled:1.
2025-01-05T16:58:35Z.0 [s]ession...... compiled:1 enabled:1.
2025-01-05T16:58:35Z.0 [p]rotocol..... compiled:1 enabled:0.
2025-01-05T16:58:35Z.0 [x]proxy....... compiled:1 enabled:0.
2025-01-05T16:58:35Z.0 [r]emote....... compiled:1 enabled:1.
2025-01-05T16:58:35Z.0 [f]ault........ compiled:1 enabled:1.
2025-01-05T16:58:35Z.0 [q]uitting..... compiled:1 enabled:0.
2025-01-05T16:58:35Z.0 [o]bjects...... compiled:1 enabled:0.
2025-01-05T16:58:35Z.0 [v]erbose...... compiled:1 enabled:0.
2025-01-05T16:58:35Z.0 Press CTRL-C to stop the node.
Segmentation fault
evoskuil20:54
I didn't really change anything except for reporting the full error code. Did it just work?
evoskuil21:05
Re the segfault, This commit includes a number of unverified changes. I'm working through a significant bunch of changes. I suggest working form this one until I can verify them (though I'm not sure if this remains in sync with other repos, as they have advanced as well).
We have release branches for this reason. Working form master can be a challenge because it changes quickly.
https://github.com/libbitcoin/libbitcoin-node/pull/704/commits/3fe83b9e1236e35f7451342cf82cd709dc04d91f
evoskuil21:12
It's also possible there's a problem unique to Linux, but there wasn't the last time I synced there. @cguida should be setting up an Ubuntu build, debug and perf analysis environment soon.
evoskuil21:28
I'm also curious about your build process. Are you using the node repository install.sh or are you building manually and incrementally?
evoskuil22:20
Yeah, I have my build PC on wifi this week, so haven't been runtime testing. xmas tree took my workspace. 😅
😂 1
evoskuil22:28
2025-01-05T22:27:32Z.0 Press CTRL-C to stop the node.
2025-01-05T22:27:32Z.0 Please wait while network is starting...
2025-01-05T22:27:32Z.1 Candidate top [000000000019d6689c085ae165831e934ff763ae46a2a6c172b3f1b60a8ce26f:0].
2025-01-05T22:27:32Z.1 Fork point (0) unassociated (0).
2025-01-05T22:27:33Z.1 Loaded (50000) addresses.
2025-01-05T22:27:33Z.1 Bypassed seeding because outbound connections disabled.
2025-01-05T22:27:33Z.0 Node is started.
2025-01-05T22:27:33Z.1 Not configured for inbound connections.
2025-01-05T22:27:33Z.1 Not configured for outbound connections.
2025-01-05T22:27:33Z.0 Node is running.
evoskuil22:29
Yeah, that was it. Just wait for the most recent node PR and rerun the full install (other repos are changed too).
evoskuil22:35
evoskuil22:37
Not because of concurrency. Constructors have initializer lists, for class member variables and base classes.
evoskuil22:37
The cpp listed order is not the order of the initialization, which is deceptive. Every once in a while I miss it.
evoskuil22:38
So the threadpool init got moved to after the strand init, which takes the threadpool. Even though in the CPP file they are listed in the correct order (before and after the change).
👍 1
evoskuil22:39
So this was a problem:
    // These are thread safe.
    const bool concurrent_;
    const size_t maximum_backlog_;
    const uint64_t initial_subsidy_;
    const uint32_t subsidy_interval_;
    network::asio::strand independent_strand_;

    // These are protected by strand.
network::threadpool threadpool_;evoskuil22:40
I try to group the members by thread safe and not thread safe. It's important to keep track of those that are not. But they don't always group so nicely into two groups and also the required order. Takes some creativity.
evoskuil22:51
I was telling you that the cache defaults to 10k entries before. It actually defaults to 50k unique entries. Are there that many nodes on the network? It builds this in almost no time from the network.
C
cguida22:53
according to bitnodes, there are like 20k listening nodes, but there's a whole lot more that aren't listening
evoskuil23:17
If they aren't listening then you can't connect to them, in which case they should not be publishing their addresses.
👍 1
evoskuil23:56
block	txs	%
000k	1	0.00%
050k	50,780	0.00%
100k	216,577	0.02%
150k	1,718,407	0.17%
200k	7,316,696	0.71%
250k	21,491,097	2.08%
300k	38,463,787	3.73%
350k	63,960,713	6.20%
400k	112,477,764	10.90%
450k	190,757,159	18.48%
500k	283,595,037	27.47%
550k	356,588,225	34.54%
600k	466,297,403	45.17%
650k	571,876,797	55.40%
700k	669,566,380	64.86%
750k	757,720,472	73.40%
800k	868,965,224	84.18%
850k	1,032,289,555	100.00%
evoskuil23:58
But that's fine, we know it's slow on linux/osx. First step is just complete a milestone run. Don't worry about validation.
To be clear, this is not a benchmark. This is development. I won't support any numbers that come out of linux/osx until we've optimized on those platforms. I've only run each of them one time.
👍 1
evoskuil00:01
BTW, this is a side thread from #general that @Marnix created. We should prob. reset. Slack threading blows.
👍 1
M
Marnix00:40
One thing at a time. What happened with the directory question?
This was a new run on a fresh deb12 environment.
M
Marnix00:41
I'm also curious about your build process. Are you using the node repository install.sh or are you building manually and incrementally?
yes clone node repo and run install script
M
Marnix00:44
No issues with the path?
Specifying the/a different dir you mean? I didn't try, was afk then and now decided to do again on fresh OS env
evoskuil00:45
Ok, well let me know if it pops up again. These things tend to keep coming back until they're figured out. I've never seen that but I'm mostly on Windows these days.
evoskuil00:45
You could post an issue to the node repo. https://github.com/libbitcoin/libbitcoin-node/issues
M
Marnix00:48
Yes will open gh issue next time I run into something. This was in reply to your question if I could run again
evoskuil00:49
Yeah, you could try and reproduce it., change the directory, etc. I added the full error message output to the latest build. It should be fine to run now. @cguida is running latest.
evoskuil19:32
I've also looked into a design issue pertaining to neutrino filters. Way back during table design I settled on a consolidated neutrino filters table, for the filter and filer head. These can be computed at the same time, but the filter can be computed at validation time (concurrently, partial block order) and the head must be computed from the previous head (total block order). Because this filter requires the full block and prevouts it only makes sense to compute it during validation, but the head cannot be computed until confirmation. So I'm adding a
neutrino_head table (simple height-based array) and renaming the other to neutrino_filter. This will then be a complete/functional feature.👍 1
evoskuil19:33
replied to a thread: view
There's no fix unless you took a snapshot (which you didn't) so you have to resync.
evoskuil19:35
replied to a thread: view
I don't know what the issue with the test query was, but it's a fairly lengthy ad-hoc piece of temporary code, so not surprising.
evoskuil19:36
replied to a thread: view
Running it at the console, for the current query, causes a massive dump to the console, but that should be ok. I'll look at it and see if there's anything obvious.
evoskuil21:19
I just realized that when we populate prevouts from the block itself, which according to recent testing reported here as about 9% of spends, there is no need to perform confirmation checks on those prevouts, with the exception of relative locktime (bip68). That is typically a contextual check performed at confirmation because it requires prevout context (height/mtp). However relative locktime is relative. All height/mtp checks subtract prevout from spender height/mtp values, so for internal spends age is always zero. So if the relevant relative locktime specified is nonzero, the input is locked (making the tx unconfirmable in any block that activates bip68). So basically we can add this check to
void block.populate() and have it return bool if any input is locked.This means we can eliminate 9% of all confirmation checks, which is a pretty significant savings in processing, disk activity, memory, and prevout cache storage.
(edited)evoskuil21:26
It is also possible to move this to a static check, as it requires no prevouts. So it can be performed immediately upon download (when validating, where we perform
block.check(context)). We already perform is_forward_reference and is_internal_double_spend in block.check(), which are similar.evoskuil22:46
I think that leveraging these existing checks will add additional cost and/or complexity that's not worth it, and adding a new check function would be an unnecessary perf hit to
block.check(). If usually feels like we should invalidate anything that we can as early as well can, but that doesn't always hold up. I've removed some early consensus checks because they are redundant with ones later on, because the early exit on the rare case isn't worth the performance hit on the billions of checks case.So I'll just add this check to
block.populate(), which makes it simple and basically free. If this isn't called then standard database checks would take over. I tested this last month (without this locktime aspect) and it was a nice little boost, but this will be a big boost, because it eliminates 9% of confirmation with no tradeoff. And I almost overlooked it. I was going to disable the block.populate() call so that we would get prevout.tx metadata necessary for caching!evoskuil23:07
Also just realized that the
is_coinbase(prevout) check can be performed in store.populate(block) and set on the prevout metadata, along with the parent tx. This is easily derived from the tx, but by placing the call here it is performed in a normalized manner and during validation (concurrent) and the resulting bit can be set in the cache at no cost. Removing a call per prevout from every input in the chain (2.6B) during confirmation (sequentially). That cuts the cost by the number of cores. Another win.Sunday, January 5, 2025
evoskuil22:56
I've finished the work in the node (validator and confirmer) to incorporate the new prevouts table (and the split neutrino table). Also all changes complete to system::chain types in system repo, to compute locktime violations for block-internal spends, and to provide proper metadata names (using unions on existing metadata) for the database to place metadata derived from populate (during validation) and to read it during creation on the prevouts table. So basically it's all done except for updating the database tables and queries. The queries are all stubbed in and called by the node.
🔥 1
Tuesday, January 7, 2025
evoskuil18:48
The expandable-header table database primitives required for the new cache table is complete and tested. This is a new type
array_map to complement the existing hash_map and simple_array types. The new table is indexed by a positional array, which provides an insertion sort capability with O(1). There is no search to create or to retrieve from the sorted table, with elements being inserted out of order. This is because the insertion code has knowledge of the ordinal position (height) when inserting. As all tables it is append only with a random access head.
The main distinctions are that the head may expand, and there is no hash function or conflict lists (not a hashmap). The header indexes blobs of data by candidate block height, written out of order. This required the introduction of a second head type (hash_head and array_head) and a second map type (hashmap and arraymap) to produce a second table type (hash_map and array_map). The old array_map is renamed to array_simple as it was not actually a map.
Test are complete and moving on to the creation of the new table/header instance via config and the store.C
cguida19:14
@pmienk @evoskuil how do you guys usually modify the build system for
bn? I'm trying to add tracy to the build system, but the install.sh I've been using to build bn does not seem to respect the changes I've made to Makefile.am. The install script just clones 4 repos and puts them in build-libbitcoin-node. Do I need to manually alter these repos? Or is there some way to add a source file to the build process for all 4 at once?There is CI for libbitcoin-build, which might be helpful to observe.
We wouldn't want to require the package to perform builds, and we probably only want to add it to the vscode builds where there are binary outputs that we want to profile (eg node, server).

pmienk19:34
On Linux that's conditional build or debug use. Gimme a minute and I can get free for a few
pmienk19:36
@cguida you're just testing out the modification? And are attempting to build local and failing to pick up changes, correct?
@evoskuil ie
--performance-analysis or some such37 replies · evoskuil, pmienk, cguida · last Jan 08, 2025
evoskuil19:55
Yeah, pref shorter. The tool is called tracy, maybe
--tracer. I'm not sure what works yet, but might be nice to pull and build it and just have it integrated into vscode ux.pmienk19:56
maybe
--with-tracy just to follow our dependency pattern? wouldn't really matter but then in the code the flag would be pretty clear and consistent👍🏻 1
evoskuil20:06
It's not a dependency though, it's a tool that's applied at the test or console project (I think). The VS profiling tools don't require any source instrumentation, but I think Tracy does require a symbol defined in the sources.
pmienk20:09
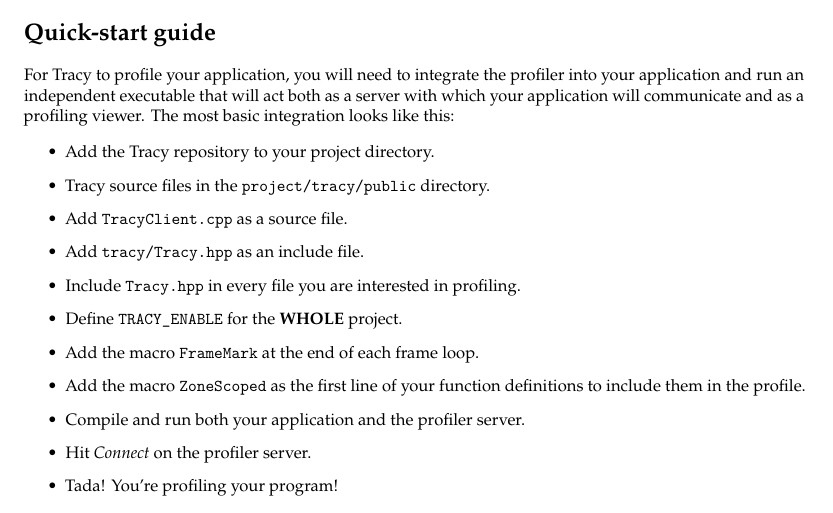
"Add the macro ZoneScoped as the first line of your function definitions to include them in the profile"
evoskuil20:11
I read on it and I thought that they had said the instrumentation was one include and that's it.
evoskuil20:12
Adding a macro to every function is a ridiculous way to discover performance hotspots.
(edited)evoskuil20:14
In the VS profiler it doesn't require a debug build, we can attach to the running process remotely, and there is no source instrumentation.
evoskuil20:20
There's a good tool integrated with xcode. Otherwise this one is the only other I found outside of VS.
C
cguida02:16
I watched a bit of the video linked on their github and the guy does a whole walkthrough on it
C
cguida02:20
https://libbitcoin.slack.com/archives/C6LH74ACQ/p1736282118292719?thread_ts=1736278617.939899&cid=C6LH74ACQ
it definitely affects performance, but i think the idea is we wouldn't build it in unless the
--with-tracy option were included
it claims to be "low overhead" fwiw, but yeah this is a debugging toolEric Voskuil
It's hard to imagine however that this won't affect performance.
C
cguida02:32
Presumably I can just throw it in something super high-level like
main() or something? Haha15 minutes
pmienk19:47
@cguida - If you're just looking to execute
install.sh with modifications to the the final project of the installer, github actions provides the environment defintion CI equal to true which the script uses to alter behavior there and can be done locally with the appropriate directory locations. problem is it's going to resync every other project you have if you're storing your sources/changes in the same location.@cguida For this reason, I manage my development in linux using
developer_setup.sh (I really should shorten it to just dev.sh). it is generated by the libbitcoin-build project just like install.sh . All install scripts: install.sh, install-cmake.sh, install-cmakepresets.sh and developer_setup.sh share a common codebase with what I hope to be minor tweaks. developer_setup.sh allows for greater granularity of control, allowing you to execute a build against your local repositories.
If and when you have a build with tracy working, we'll then have to fold any changes you've made in the make and config systems into the generation of those artifacts and make sure appropriate mechanisms for cmake are supplied.157 replies · cguida, pmienk · last Jan 16, 2025
C
cguida19:59
ok great, this is what i was looking for! just need a way to rebuild repeatedly until stuff works, then once i get it working i can look into adding something a bit more "official"
pmienk20:01
just gotta generate it locally with
gsl --script:template/gsl.developer_setup.sh generate4.xml
chmod +x output/*/developer_setup.sh
then copy the one you want and properly parameterize. I didn't default src or obj directories, so its a little noisy on the command line
(edited)🙏 1
pmienk20:02
you can see an example of it being used to build a docker container for bs in the docker subdirectory
pmienk20:25
(oddly, on arch i didn't install it and everything built and runs fine... so i'm not sure how i satisfied that dependency)
pmienk20:27
on arch, the prce package adds the dev files, maybe i've just had it go in a package update without specifying it as necessary
pmienk20:29
you could run it from the docker container zeromq provides. though an alias isn't picked up in script unless you modify your environment, set +<can't remember what>
pmienk20:32
eh, i can edit -build to define GSL=gsl if not defined, GSL=docker run... in an environment would take it from there... seems pretty easy
C
cguida20:33
$ sudo apt install libpcre3-dev
[sudo] password for cguida:
Package libpcre3-dev is not available, but is referred to by another package.
This may mean that the package is missing, has been obsoleted, or
is only available from another source

Error: Package 'libpcre3-dev' has no installation candidate
C
cguida20:37
$ apt search pcre
awffull/testing 3.10.2-10 amd64
web server log analysis program
cl-abnf/testing 20200229.gitba1fbb1-1 all
Common Lisp ABNF parser generator
cl-ppcre/testing 20240427.git80fb19d-1 all
Portable Perl-compatible regular expressions for Common Lisp
cl-ppcre-unicode/testing 20240427.git80fb19d-1 all
Portable Perl-compatible regular expressions for Common Lisp (Unicode)
cl-unicode/testing 20231118.git07e7ff5-1 all
portable Unicode library for Common Lisp
elpa-pcre2el/testing 1.12-2 all
Emacs mode to convert between PCRE, Emacs and rx regexp syntax
exonerate/testing 2.4.0-5+b1 amd64
generic tool for pairwise sequence comparison
gambas3-gb-pcre/testing 3.19.5-1 amd64
Gambas regexp component
libapache2-mod-php8.2/testing 8.2.27-1 amd64
server-side, HTML-embedded scripting language (Apache 2 module)
libghc-regex-base-dev/testing 0.94.0.2-3 amd64
GHC library providing an API for regular expressions
libghc-regex-base-doc/testing 0.94.0.2-3 all
GHC library providing an API for regular expressions; documentation
libghc-regex-base-prof/testing 0.94.0.2-3 amd64
GHC library providing an API for regular expressions; profiling libraries
libhyperscan5/testing 5.4.2-3 amd64
High-performance regular expression matching library
libpcre2-16-0/testing,now 10.44-5 amd64 [installed,automatic]
New Perl Compatible Regular Expression Library - 16 bit runtime files
libpcre2-32-0/testing,now 10.44-5 amd64 [installed,automatic]
New Perl Compatible Regular Expression Library - 32 bit runtime files
libpcre2-8-0/testing,now 10.44-5 amd64 [installed]
New Perl Compatible Regular Expression Library- 8 bit runtime files
libpcre2-dev/testing,now 10.44-5 amd64 [installed]
New Perl Compatible Regular Expression Library - development files
libpcre2-ocaml/testing 8.0.2-1 amd64
OCaml bindings for PCRE2 (runtime)
libpcre2-ocaml-dev/testing 8.0.2-1 amd64
OCaml bindings for PCRE2 (Perl Compatible Regular Expression)
libpcre2-posix3/testing,now 10.44-5 amd64 [installed,automatic]
New Perl Compatible Regular Expression Library - posix-compatible runtime files
libphp8.2-embed/testing 8.2.27-1 amd64
HTML-embedded scripting language (Embedded SAPI library)
libre2-11/testing,now 20240501-3+b1 amd64 [installed,automatic]
efficient, principled regular expression library
libre2-dev/testing 20240501-3+b1 amd64
efficient, principled regular expression library, development kit
libre2j-java/testing 1.7+dfsg-1 all
RE2/J: linear time regular expression matching in Java
librust-grep-pcre2-dev/testing 0.1.8-1 amd64
Use PCRE2 with the 'grep' crate - Rust source code
librust-pcre2-dev/testing 0.2.6-1+b2 amd64
High level wrapper library for PCRE2 - Rust source code
librust-pcre2-sys-dev/testing 0.2.7-1+b1 amd64
Low level bindings to PCRE2 - Rust source code
libvectorscan5/testing 5.4.11-2+b1 amd64
Portable fork of Intel's Hyperscan library
lua-rex-pcre2/testing 2.9.2-3+b1 amd64
Perl regular expressions library (PCRE2) for the Lua language
lua-rex-pcre2-dev/testing 2.9.2-3+b1 amd64
PCRE2 development files for the Lua language
mle/testing 1.7.2-1 amd64
flexible terminal-based editor
pcre2-utils/testing 10.44-5 amd64
New Perl Compatible Regular Expression Library - utilities
php-composer-pcre/testing 3.3.2-1 all
PCRE wrapping library that offers type-safe preg_* replacements
php8.2-cgi/testing 8.2.27-1 amd64
server-side, HTML-embedded scripting language (CGI binary)
php8.2-cli/testing 8.2.27-1 amd64
command-line interpreter for the PHP scripting language
php8.2-fpm/testing 8.2.27-1 amd64
server-side, HTML-embedded scripting language (FPM-CGI binary)
php8.2-phpdbg/testing 8.2.27-1 amd64
server-side, HTML-embedded scripting language (PHPDBG binary)
postfix-pcre/testing 3.9.1-9 amd64
PCRE map support for Postfix
postgresql-17-pgpcre/testing 0.20190509-8+b1 amd64
Perl Compatible Regular Expressions (PCRE) extension for PostgreSQL
prelude-lml-rules/testing 5.2.0-1 all
Security Information and Events Management System [ LML Rules ]
python3-pcre2/testing 0.4.0+ds-1 amd64
Python bindings for the PCRE2 regular expression library
regexxer/testing 0.10-6+b1 amd64
visual search and replace tool using Perl Regex
ruby-re2/testing 2.7.0-2 amd64
Ruby bindings to re2
varnish-re2/testing 2.0.0-6 amd64
RE2 regular expressions for Varnish
C
cguida20:45
eyyyy
$ gsl
GSL/4.1.5 Copyright (c) 1996-2016 iMatix Corporation
              GSL Developers 2016-2017
syntax: gsl -<option> ... -<attr>[:<value>] ... <filename> ...
    or: gsl -a -<option> ... -<attr>[:<value>] <filename> <arg> ...
    Options:
    -a          argument:  Pass arguments following filename to GSL script
    -q          quiet:     suppress routine messages
    -p          parallel:  process files in parallel
    -c:m[:file] console:   set console mode (optionally capture output to file)
                           (use capital case -C:... to disable the echo)
                               mode:
                                   p   - print as requested
                                   d   - prefix with date and time
                                   t   - prefix with time only
                                   dbg - datetime, with full flush to disk
    -s:n     size:n        set script cache size - default is 1000000
    -h       help:         show command-line summary
-v version: show full version informationC
cguida21:07
which repo should i run that command in?
2025-01-09 14:11:02 cguida@cg-carbon:~/code/libbitcoin-node$ gsl --script:template/gsl.developer_setup.sh generate4.xml
GSL/4.1.5 Copyright (c) 1996-2016 iMatix Corporation
              GSL Developers 2016-2017
gsl/4 I: Processing generate4.xml...
gsl/4 E: Error processing generate4.xml...
Could not find XML file: generate4.xml
C
cguida21:08
2025-01-09 15:07:10 cguida@cg-carbon:~/code/libbitcoin-build$ gsl --script:template/gsl.developer_setup.sh generate4.xml
GSL/4.1.5 Copyright (c) 1996-2016 iMatix Corporation
              GSL Developers 2016-2017
gsl/4 I: Processing generate4.xml...
No script specified. (edited)C
cguida21:10
oh i guess maybe follow this? https://github.com/libbitcoin/libbitcoin-build?tab=readme-ov-file#linux
C
cguida21:15
still getting this
$ gsl --script:templates/gsl.developer_setup.sh generate4.xml
GSL/4.1.5 Copyright (c) 1996-2016 iMatix Corporation
              GSL Developers 2016-2017
gsl/4 I: Processing generate4.xml...
No script specified.
C
cguida21:19
ok this seems to have worked
$ gsl templates/gsl.developer_setup.sh generate4.xml
GSL/4.1.5 Copyright (c) 1996-2016 iMatix Corporation
              GSL Developers 2016-2017
gsl/4 I: Processing templates/gsl.developer_setup.sh...

(gsl.developer_setup.sh 522) Undefined expression: generate
GSL/4.1.5 Copyright (c) 1996-2016 iMatix Corporation
              GSL Developers 2016-2017
gsl/4 I: Processing generate4.xml...

gsl/4 M: Generating output/libbitcoin-client/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-database/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-explorer/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-network/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-node/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-protocol/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-server/developer_setup.sh...
gsl/4 M: Generating output/libbitcoin-system/developer_setup.sh...pmienk21:28
so if you store all your sources under /home/user/code/libbitcoin/<libbitcoin sources>, point it to /home/user/code/libbitcoin
C
cguida21:30
--build-mode=<value> Specifies minimum action to be taken.
Valid values: { sync, configure, build }.
Defaults to 'unknown', must be declared.
pmienk21:31
sync will blow away and resync your repos, configure will reconfigure the builds with new params stated on command line, build will try to reuse everything including the objs - just like rekicking off to fix a compiler error
C
cguida21:33
$ ls docker/
bs-linux.Dockerfile bs-linux.env.in bs-linux.sh bs-linux-startup.sh bs-linux.yml README.md
2025-01-09 15:33:21 cguida@cg-carbon:~/code/libbitcoin-build$
pmienk21:44
yeah, it's a perfectly useable example. i may have factored it a bit in my repo which shows off some additional control... think i was going to pair out the extraneous commands before a pull
pmienk21:46
if you're trying to go against master though, i'd use the -node copy as server hasn't been updated on master
C
cguida21:46
hmm weird
/usr/include/c++/14/cstdlib:79:15: fatal error: stdlib.h: No such file or directory
   79 | #include_next <stdlib.h>
pmienk21:53
i'd check https://github.com/libbitcoin/libbitcoin-node/blob/master/.github/workflows/ci.yml if you're looking for build environment issues.
👍 1
C
cguida19:10
Hmm still hitting this error.
The error occurs while trying to build libbitcoin-system. I've checked the dockerfile for bx-linux https://github.com/libbitcoin/libbitcoin-build/blob/master/docker/bx-linux.Dockerfile
I've checked the ci.yml file https://github.com/libbitcoin/libbitcoin-node/blob/master/.github/workflows/ci.yml
Nothing really jumps out at me as to why I'd be missing dependencies.
Ftr when I run ./install.sh from libbitcoin-node, the node builds just fine, so I guess it's just something configured differently in
developer_setup.sh 😕C
cguida19:55
$ ./developer_setup.sh     --enable-isystem     --without-consensus     --with-icu     --build-icu     --build-boost     --build-zmq     --build-mode=configure     --build-target=all     --build-src-dir=$PWD/src     --build-obj-dir=$PWD/obj     --prefix=$PWD/prefix     --disable-shared     --enable-static
libbitcoin-node installer configuration.
--------------------------------------------------------------------
OS                    : Linux
PARALLEL              : 14
CC                    :
CXX                   :
CPPFLAGS              :
CFLAGS                :
CXXFLAGS              :
LDFLAGS               :
LDLIBS                :
WITH_ICU              : yes
BUILD_ICU             : yes
BUILD_BOOST           : yes
BUILD_SECP256K1       :
BOOST_ROOT            : /home/cguida/code/libbitcoin/prefix
BUILD_SRC_DIR         : /home/cguida/code/libbitcoin/src
BUILD_OBJ_DIR         : /home/cguida/code/libbitcoin/obj
BUILD_MODE            : configure
BUILD_TARGET          : all
SYNC_ONLY             :
PREFIX                : /home/cguida/code/libbitcoin/prefix
DISABLE_SHARED        : yes
DISABLE_STATIC        :
with_boost            : --with-boost=/home/cguida/code/libbitcoin/prefix
with_pkgconfigdir     : --with-pkgconfigdir=/home/cguida/code/libbitcoin/prefix/lib/pkgconfig
--------------------------------------------------------------------

********************** Initialize git **********************
Reinitialized existing Git repository in /home/cguida/code/libbitcoin/src/.git/

********************** Initialize object directory **********************
Reinitializing /home/cguida/code/libbitcoin/obj...
Initializing directory /home/cguida/code/libbitcoin/obj...

********************** Create local copies of required libraries **********************

********************** Preparing to acquire icu4c-55_2-src.tgz **********************
Reusing existing archive icu4c-55_2-src.tgz...

********************** Preparing to acquire boost_1_78_0.tar.bz2 **********************
Reusing existing archive boost_1_78_0.tar.bz2...

********************** Preparing to acquire libbitcoin/libbitcoin-system/master **********************
Reusing existing clone of libbitcoin/libbitcoin-system, Branch may not match master...

********************** Preparing to acquire libbitcoin/libbitcoin-network/master **********************
Reusing existing clone of libbitcoin/libbitcoin-network, Branch may not match master...

********************** Preparing to acquire libbitcoin/libbitcoin-database/master **********************
Reusing existing clone of libbitcoin/libbitcoin-database, Branch may not match master...

********************** Preparing to acquire libbitcoin/libbitcoin-node/master **********************
Reusing existing clone of libbitcoin/libbitcoin-node, Branch may not match master...

********************** Build local copies of required libraries **********************

********************** Preparing to build icu4c-55_2-src.tgz **********************
pmienk19:56
Yes, standard out and error, along with the parameters passed. When I get a free minute I'll spin up a trixie container and try with your distro if we can't track it down otherwise
C
cguida19:58
out.txt
$ ./developer_setup.sh     --enable-isystem     --without-consensus     --with-icu     --build-icu     --build-boost     --build-zmq     --build-mode=configure     --build-target=all     --build-src-dir=$PWD/src     --build-obj-dir=$PWD/obj     --prefix=$PWD/prefix     --disable-shared     --enable-static
libbitcoin-node installer configuration.
--------------------------------------------------------------------
OS                    : Linux
PARALLEL              : 14
CC                    :
CXX                   :
CPPFLAGS              :
CFLAGS                :
CXXFLAGS              :
LDFLAGS               :
LDLIBS                :
WITH_ICU              : yes
BUILD_ICU             : yes
BUILD_BOOST           : yes
BUILD_SECP256K1       :
BOOST_ROOT            : /home/cguida/code/libbitcoin/prefix
BUILD_SRC_DIR         : /home/cguida/code/libbitcoin/src
BUILD_OBJ_DIR         : /home/cguida/code/libbitcoin/obj
BUILD_MODE            : configure
BUILD_TARGET          : all
SYNC_ONLY             :
PREFIX                : /home/cguida/code/libbitcoin/prefix
DISABLE_SHARED        : yes
DISABLE_STATIC        :
with_boost            : --with-boost=/home/cguida/code/libbitcoin/prefix
with_pkgconfigdir     : --with-pkgconfigdir=/home/cguida/code/libbitcoin/prefix/lib/pkgconfig
--------------------------------------------------------------------

********************** Initialize git **********************
Reinitialized existing Git repository in /home/cguida/code/libbitcoin/src/.git/

********************** Initialize object directory **********************
Reinitializing /home/cguida/code/libbitcoin/obj...
Initializing directory /home/cguida/code/libbitcoin/obj...

********************** Create local copies of required libraries **********************

********************** Preparing to acquire icu4c-55_2-src.tgz **********************
Reusing existing archive icu4c-55_2-src.tgz...
full file
C
cguida20:01
C
cguida20:01
out.log
$ ./developer_setup.sh     --enable-isystem     --without-consensus     --with-icu     --build-icu     --build-boost     --build-zmq     --build-mode=configure     --build-target=all     --build-src-dir=$PWD/src     --build-obj-dir=$PWD/obj     --prefix=$PWD/prefix     --disable-shared     --enable-static
libbitcoin-node installer configuration.
--------------------------------------------------------------------
OS                    : Linux
PARALLEL              : 14
CC                    :
CXX                   :
CPPFLAGS              :
CFLAGS                :
CXXFLAGS              :
LDFLAGS               :
LDLIBS                :
WITH_ICU              : yes
BUILD_ICU             : yes
BUILD_BOOST           : yes
BUILD_SECP256K1       :
BOOST_ROOT            : /home/cguida/code/libbitcoin/prefix
BUILD_SRC_DIR         : /home/cguida/code/libbitcoin/src
BUILD_OBJ_DIR         : /home/cguida/code/libbitcoin/obj
BUILD_MODE            : configure
BUILD_TARGET          : all
SYNC_ONLY             :
PREFIX                : /home/cguida/code/libbitcoin/prefix
DISABLE_SHARED        : yes
DISABLE_STATIC        :
with_boost            : --with-boost=/home/cguida/code/libbitcoin/prefix
with_pkgconfigdir     : --with-pkgconfigdir=/home/cguida/code/libbitcoin/prefix/lib/pkgconfig
--------------------------------------------------------------------

********************** Initialize git **********************
Reinitialized existing Git repository in /home/cguida/code/libbitcoin/src/.git/

********************** Initialize object directory **********************
Reinitializing /home/cguida/code/libbitcoin/obj...
Initializing directory /home/cguida/code/libbitcoin/obj...

********************** Create local copies of required libraries **********************

********************** Preparing to acquire icu4c-55_2-src.tgz **********************
Reusing existing archive icu4c-55_2-src.tgz...
full file
C
cguida20:04
out.log
$ ./developer_setup.sh     --enable-isystem     --without-consensus     --with-icu     --build-icu     --build-boost     --build-zmq     --build-mode=configure     --build-target=all     --build-src-dir=$PWD/src     --build-obj-dir=$PWD/obj     --prefix=$PWD/prefix     --disable-shared     --enable-static
libbitcoin-node installer configuration.
--------------------------------------------------------------------
OS                    : Linux
PARALLEL              : 14
CC                    :
CXX                   :
CPPFLAGS              :
CFLAGS                :
CXXFLAGS              :
LDFLAGS               :
LDLIBS                :
WITH_ICU              : yes
BUILD_ICU             : yes
BUILD_BOOST           : yes
BUILD_SECP256K1       :
BOOST_ROOT            : /home/cguida/code/libbitcoin/prefix
BUILD_SRC_DIR         : /home/cguida/code/libbitcoin/src
BUILD_OBJ_DIR         : /home/cguida/code/libbitcoin/obj
BUILD_MODE            : configure
BUILD_TARGET          : all
SYNC_ONLY             :
PREFIX                : /home/cguida/code/libbitcoin/prefix
DISABLE_SHARED        : yes
DISABLE_STATIC        :
with_boost            : --with-boost=/home/cguida/code/libbitcoin/prefix
with_pkgconfigdir     : --with-pkgconfigdir=/home/cguida/code/libbitcoin/prefix/lib/pkgconfig
--------------------------------------------------------------------

********************** Initialize git **********************
Reinitialized existing Git repository in /home/cguida/code/libbitcoin/src/.git/

********************** Initialize object directory **********************
Reinitializing /home/cguida/code/libbitcoin/obj...
Initializing directory /home/cguida/code/libbitcoin/obj...

********************** Create local copies of required libraries **********************

********************** Preparing to acquire icu4c-55_2-src.tgz **********************
Reusing existing archive icu4c-55_2-src.tgz...
full file
C
cguida20:06
$ ls -al /usr/include/stdlib.h
-rw-r--r-- 1 root root 41032 Jan  3 04:56 /usr/include/stdlib.h
Phillip Mienk
And can you locate stdlib.h on your system?
C
cguida20:10
Hmm this appears to have worked. What is
isystem?
https://libbitcoin.slack.com/archives/C6LH74ACQ/p1736798779263119?thread_ts=1736279513.687499&cid=C6LH74ACQPhillip Mienk
If you can, try dropping --enable-isystem. Gotta do naptime, back in 10-20minutes
pmienk20:22
You have multiple versions of the same compiler installed side by side. isystem silences errors from dependencies by classifying them as system provided, so boost and icu stuff isn't dirtying our attempts to track down real issues. However the way its implemented (not by us) changes search order for system directories and can produce errors with multiple versions on a system
C
cguida03:01
How do you get the
build mode to go faster?
i have $ ./developer_setup.sh --without-consensus --with-icu --build-icu --build-boost --build-zmq --build-mode=build --build-target=all --build-src-dir=$PWD/src --build-obj-dir=$PWD/obj --prefix=$PWD/prefix --disable-shared --enable-static
and i built once and it took 14 minutes, then i built again without changing anything and it's still several minutes into the build. what's the option for "just rebuild the files I changed"?C
cguida03:06
i just put a line in
libbitcoin-node/console/executor_runner.cpp as a sanity check.
but then as I said, I ran the build again with no changes, and it still took a long timepmienk03:07
well, i'd suggest --build-target=project if the developer_steup.sh is from -node. that will scope to node. alternately, you could drop into the obj directories and kick off make
👍 1
pmienk03:08
not necessarily. dependencies such as icu, zmq and boost use a different flow of control. I would suggest dropping their build instruction after establishing a prefix. you'll need to then specify --with-boost=<prefix path> or define BOOST_ROOT environmentally
C
cguida03:09
ah this must be why
--enable-static
--enable-static
Reusing configuration for /home/cguida/code/libbitcoin/src/libbitcoin-node...
Requested 'make clean'...
 rm -f console/bn
 rm -f test/libbitcoin-node-test
test -z "src/libbitcoin-node.la" || rm -f src/libbitcoin-node.la
rm -f src/so_locations
rm -rf .libs _libs
rm -rf console/.libs console/_libs
rm -rf src/.libs src/_libs
rm -rf src/chasers/.libs src/chasers/_libs
rm -rf src/protocols/.libs src/protocols/_libs
rm -rf src/sessions/.libs src/sessions/_libs
rm -rf test/.libs test/_libs
rm -rf tracy/public/.libs tracy/public/_libs
rm -f *.o
rm -f console/*.o
rm -f src/*.o
rm -f src/*.lo
rm -f src/chasers/*.o
rm -f src/chasers/*.lo
rm -f src/protocols/*.o
rm -f src/protocols/*.lo
rm -f src/sessions/*.o
rm -f src/sessions/*.lo
rm -f test/*.o
rm -f test/chasers/*.o
rm -f test/protocols/*.o
rm -f test/sessions/*.o
rm -f tracy/public/*.o
rm -f tracy/public/*.lo
test -z "libbitcoin-node-test_runner.sh.log" || rm -f libbitcoin-node-test_runner.sh.log
test -z "libbitcoin-node-test_runner.sh.trs" || rm -f libbitcoin-node-test_runner.sh.trs
pmienk03:09
yeah, can't guarantee there isn't an errant make clean in there. I noticed it awhile ago but haven't had bandwidth to track it down.
👍 1
pmienk03:10
shouldn't be kicked off when -mode=build but there were some original checks that were miswritten and it may predate a refinement of my understanding of the scripting language.
pmienk03:11
as few people have inquired as to how to do what your doing and even fewer asked questions, I'm really the only one who uses these tools regularly
👍 1
C
cguida03:14
yeah there's definitely a
make_jobs true in the make_project_directory function in developer_setup.sh
true sets "preclean" to true which runes the make cleanC
cguida03:15
C
cguida03:17
so if i switch to project and change that line to
(edited)make_jobs false, then i don't get a make cleanpmienk03:19
sort of. without looking deeper,
make_jobs false might break something else when build with a different mode. it's more likely a condition has to be made about the mode, calculated and passed.pmienk19:55
If you want to start out by instead adding the conditional dependency, we'd want to either go with our standard
--with-<foo> pattern enabling the presence and respecting those flags - which could be as little as modifying the generate4.xml or as large as editing templates for configure.ac, Makefile.am , CMakeLists.txt, and the pkg-config artifactsThursday, January 9, 2025

jungly07:07
The news about Nvidia's new project is so exciting. Imagine running libbitcoin on it. 128 GB ram and at least 72 cores iiuc. It'll be interesting to know if we'll need to program with the GPU or not?
https://www.nvidia.com/en-us/data-center/grace-cpu-superchip/
https://nvidianews.nvidia.com/news/nvidia-puts-grace-blackwell-on-every-desk-and-at-every-ai-developers-fingertips
NVIDIA Newsroom
CES—NVIDIA today unveiled NVIDIA® Project DIGITS, a personal AI supercomputer that provides AI researchers, data scientists and students worldwide with access to the power of the NVIDIA Grace ...
🔥 1
1 reply · evoskuil · last Jan 11, 2025

neillm18:55
Hey all -- I could probably meet today if anyone's around in ~10-15m. If not, no worries, maybe next week?
3 replies · evoskuil, jungly, neillm · last Jan 14, 2025
Huddle with pmienk, cguida, Marnix · 13 min20:57
Saturday, January 11, 2025
evoskuil01:20
replied to a thread: view
The future comes fast. Optimizing for the past is never a good long term strategy.
💯 2
evoskuil03:39
Test are complete and moving on to the creation of the new table/header instance via config and the store.
The new table/header instance is now incorporated into the store, store tests and node config. Also expanded test coverage for the new database primitives. The node now manages the table as with all others (create, start, stop, backup, restore, etc).
So now just to write it from validate and read it from confirm, and incorporate the read into calling abbreviated confirmation queries.
👍 1
Monday, January 13, 2025
evoskuil06:17
I've just merged the changes to write the prevout cache for validated blocks. Only the prevout parent tx primary key and its coinbase-ness are written, and I've merged the coinbase bit into the 32 bit tx pk word (enough space for like 8 more years). I'm not sure that writing the spend pk will be necessary, but that can be quickly added.
The writes are bypassed for block-internal spends, as these spends are confirmable as long as they pass relative locktime checks, which require no chain context apart for bip68 activation. So this is checked during populate for validation. This saves about 9% of "is-confirmed" confirmation calls. No space is saved because I'm using a sentinel value to maintain prevout positions within the block. This eliminates the need for storing a count, and provides an easy correlation to spends that do not need to be checked for "is-not-double-spending", saving 9% of those confirmation calls as well.
I spend a good part of the day isolating a problem that turned out to be that I needed to check for bip68 activation before applying the relative locktime checks in populate. That's now merged and I'm running a performance test to get the performance cost of the additional writes (and relative locktime checks, which should be trivial).
Next is to adapt the confirmable query by incorporating the prevout cache, and then measure the performance change on the maxi/mini machines.
evoskuil18:33
I made a small optimization in block.populate() [avoid hash copying into
(edited)std::unordered_map using std::ref] which has at least offset the cost of writing the prevout cache. 678 secs vs 683 secs previously for the first 50k blocks validated (295k-345k) from disk.It should take about 8 hours for the mini to finish validation. At that point I'll have a good measure on the prevouts cache and will be able to start measuring the behavior of confirmation using the cache.
🔥 1
evoskuil18:55
I also incorporated the
(edited)block.fee() write into the block validated record. The write has always been there but it didn't formerly compute the actual value (sum of tx fees). So this is also coming at no additional cost. It's not required for validation/confirmation, it's just a query optimization, such as for a block explorer. It's otherwise costly because all tx output values and prevout values are required for fee computation.For tx pool txs we also will cache the
tx.fee() on each tx validated record, so that we have that value for later validation of the block reward.Finally, I've incorporated the final neutrino filter computation code into the validator, so that it will compute the filter as part of parallel validation, or in the case of checkpoint/milestone, it will compute filters in parallel while bypassing the validation checks. This also includes some optimization to bypass metadata population when obtaining prevouts for filter-only computation, since metadata is not required for filter computation. I'm not testing yet the cost of parallel filter computation, with or without validation, though I'll get to that eventually.
(edited)I still need to update the database for filters, by splitting the one table into two. And the filter head stage then gets written sequentially during confirmation.
C
cguida19:28
Still fighting with the build system, if anyone has ideas https://libbitcoin.slack.com/archives/C6LH74ACQ/p1736795438956029?thread_ts=1736279513.687499&cid=C6LH74ACQ
cguida
Hmm still hitting this error.
The error occurs while trying to build libbitcoin-system. I've checked the dockerfile for bx-linux https://github.com/libbitcoin/libbitcoin-build/blob/master/docker/bx-linux.Dockerfile
I've checked the ci.yml file https://github.com/libbitcoin/libbitcoin-node/blob/master/.github/workflows/ci.yml
Nothing really jumps out at me as to why I'd be missing dependencies.
Ftr when I run ./install.sh from libbitcoin-node, the node builds just fine, so I guess it's just something configured differently in
developer_setup.sh 😕evoskuil21:53
About 40% validated with cache writing and 10+ minutes ahead of the previous benchmark.
C
cguida22:52
you mean this one? https://libbitcoin.slack.com/archives/C6LH74ACQ/p1736749033622179
Eric Voskuil
I've just merged the changes to write the prevout cache for validated blocks. Only the prevout parent tx primary key and its coinbase-ness are written, and I've merged the coinbase bit into the 32 bit tx pk word (enough space for like 8 more years). I'm not sure that writing the spend pk will be necessary, but that can be quickly added.
The writes are bypassed for block-internal spends, as these spends are confirmable as long as they pass relative locktime checks, which require no chain context apart for bip68 activation. So this is checked during populate for validation. This saves about 9% …
Oh I see
Next is to adapt the confirmable query by incorporating the prevout cache, and then measure the performance change on the maxi/mini machines.
👍🏻 1
awesome 🔥
evoskuil22:59
There's been no negative impact from writing the cache. Actually net performance is better. This is non-download test of validation cost, all blocks read from disk. So any measurable change is real. The read cost should also be very small, as there is no hashmap search and the amount of data is very small. The amount it cuts out is very large, so I expect this to be very effective.
💥 1
Tuesday, January 14, 2025
evoskuil03:15
Completed mini validation with cache write in 7.5 hours (an hour faster than previous runs), with 7 second stop. This is without the download in both cases, which independently takes 45 minutes. I'll be updating the confirmation code tomorrow to test the reduced queries.
(edited)Thursday, January 16, 2025
6 replies · evoskuil, cguida · last Jan 16, 2025
now to figure out what to do with it...
15 replies · evoskuil, cguida · last Jan 16, 2025
C
cguida15:36
Do you have an suggestions for scopes to add to the profiler? The tutorial suggests a function that gets called 100 million times
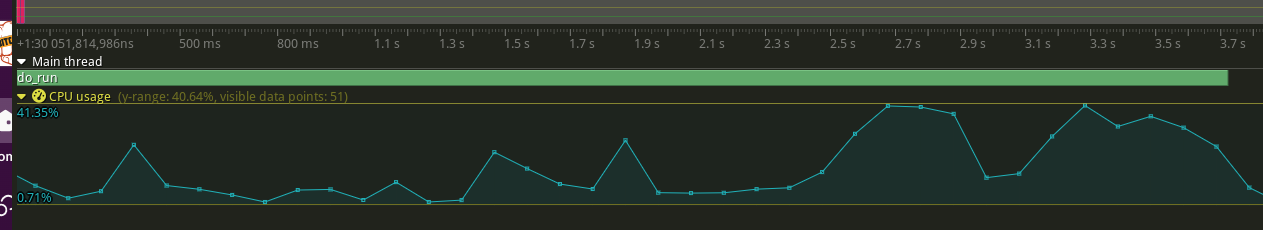
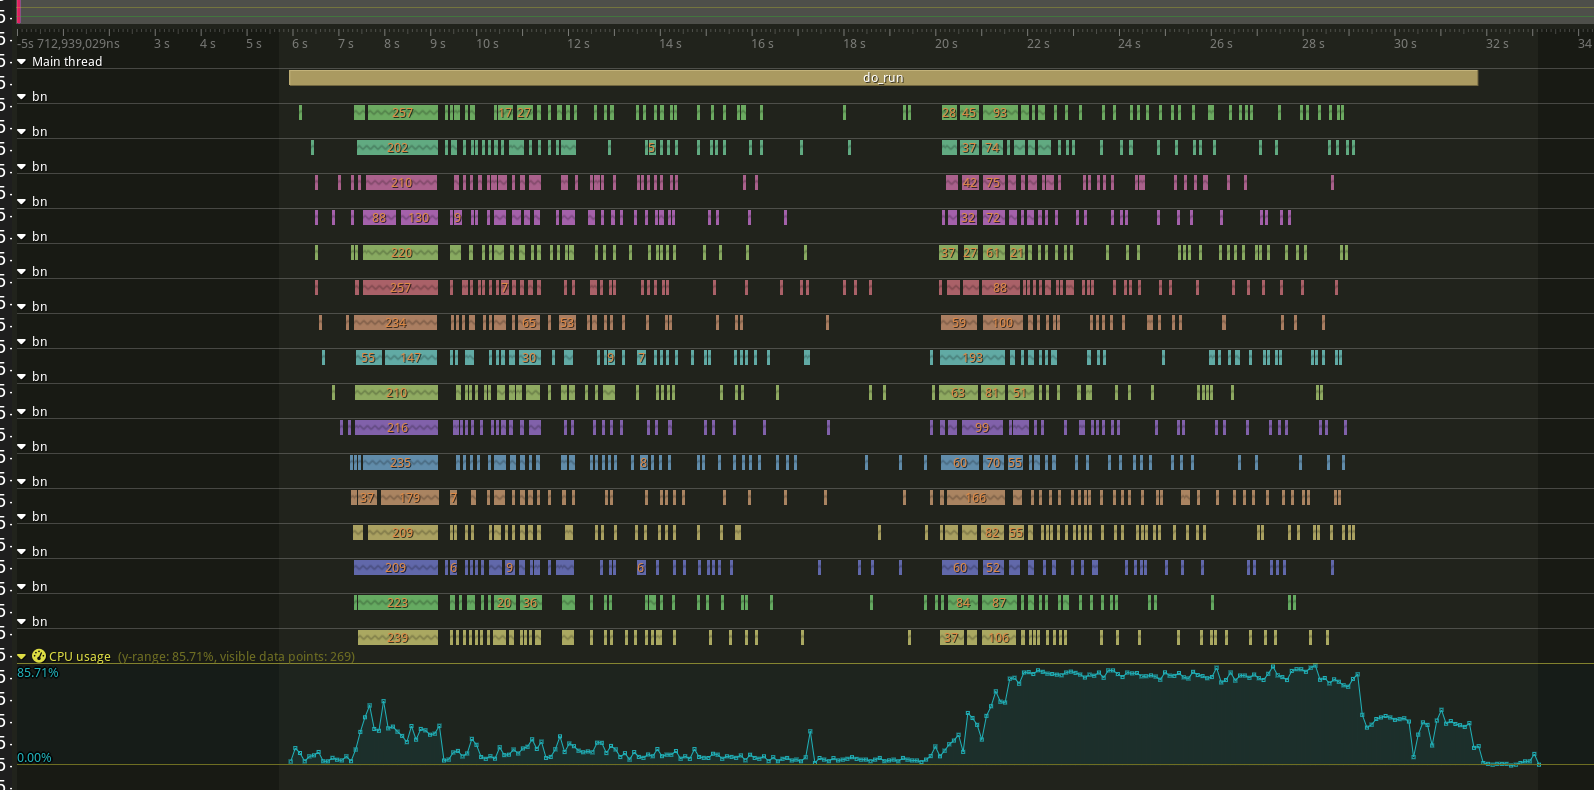
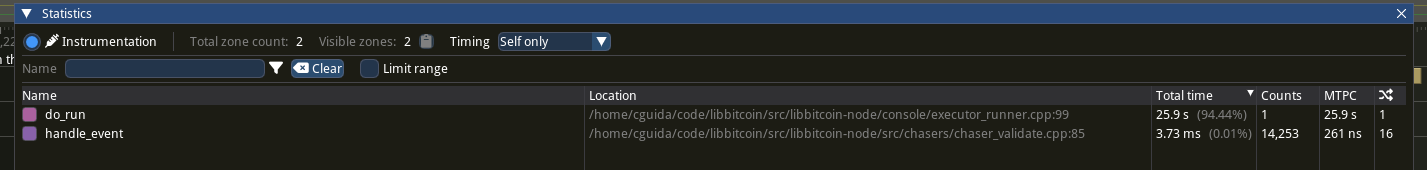
evoskuil16:07
Many things get called billions of times. But that’s prob not even the issue, since cpu utilization is very low.
evoskuil17:51
Next step is just to figure out where it’s spending 90% of its time. I would expect it to be idling somewhere, since CPU, SSD, RAM, and network are all very low utilization.
👍 1
evoskuil17:55
Idling might imply heavy lock contention, though I can’t imagine how that is the case. It’s doesn’t deadlock and there does not appear to be an issue of thread starvation. But the performance behavior is similar to what I would expect if it was running on a single (or few) thread.
(edited)👍 1
evoskuil17:58
The network thread count is determined by config alone, which is pretty simple. One thing I do in visual studio is to pause in the debugger and look at the graphical presentation of call stacks by thread. Most threads should be in some aspect of block parse or block check. If most are idling in the threadpool this would point to the problem.
👍 1
evoskuil18:00
This looks like a list of threads. If so it seems that they are very closely synchronized.
👍 1
evoskuil18:25
I don’t see that as a productive path. There are thousands of functions and none that will cause a delay like this. If they were causing the delay they would show very high cpu because they are single thread functions.
evoskuil18:26
The most costly of them are the hash accumulation invoked from bc::network::message::block::deserialize and validation in bc::system::chain::block.check() and block.check(ctx)
👍 1
C
cguida18:19
Here's that requirements file I promised a couple of weeks ago btw https://gist.github.com/chrisguida/757db02caf064d0a34a785731ea802d7
Huddle with pmienk, cguida, Marnix · 39 min20:54
C
cguida21:48
anyone know what i did wrong here?
Python 3.12.1 (main, Dec 13 2023, 14:03:38) [GCC 11.4.0] on linux
Type "help", "copyright", "credits" or "license" for more information.
>>>
>>>
>>> import zmq
>>> import struct
>>> from binascii import hexlify, unhexlify
>>>
>>>
>>> context = zmq.Context()
>>> socket = context.socket(zmq.REQ)
>>> socket.connect("tcp://mainnet.libbitcoin.net:9091")
<SocketContext(connect='tcp://mainnet.libbitcoin.net:9091')>
>>>
>>>
>>> socket
<zmq.Socket(zmq.REQ) at 0x7f5e51567540>
>>>
>>>
>>> socket.send(b'blockchain.fetch_transaction2', zmq.SNDMORE)
>>>
>>> socket.send(struct.pack('I', 42), zmq.SNDMORE)
>>>
>>>
>>> socket.send(unhexlify('60e030aba2f593caf913a7d96880ff227143bfc370d03dbaee37d582801ebd83')[::-1])
>>>
>>>
>>> response_command = socket.recv()
^CTraceback (most recent call last):
  File "<stdin>", line 1, in <module>
  File "_zmq.py", line 1156, in zmq.backend.cython._zmq.Socket.recv
  File "_zmq.py", line 1191, in zmq.backend.cython._zmq.Socket.recv
  File "_zmq.py", line 1278, in zmq.backend.cython._zmq._recv_copy
  File "_zmq.py", line 160, in zmq.backend.cython._zmq._check_rc
KeyboardInterrupt
>>>
>>>
>>> socket.recv() just hung for several minutes
took the example from here https://github.com/libbitcoin/libbitcoin-server/wiki/Python-Query-Example#short-version
pmienk22:13
my first guess would be that with zmq having removed the necessary functionality, the client you're invoking can't use the 8091 but might be able to do 8081 if that's open
I also don't know which version is running on the server, so it might have the same problem.
it would explain the hang without this being your issue
C
cguida23:02
tried 8091 on your suggestion and it hangs, same as 9091. 8081 hangs earlier, on connect
Friday, January 17, 2025
Monday, January 20, 2025
neillm03:27
$ telnet mainnet.libbitcoin.net 9091
Trying 72.65.246.83...
Connected to mainnet.libbitcoin.net.
Escape character is '^]'.
^]
telnet> quit
Connection closed.
19 replies · cguida, neillm · last Jan 28, 2025
neillm02:34
Unfortunately, not at the moment. There should be some working python code somewhere (wiki?) -- I had some working as well at one point a while back. For now, I can use
(edited)bx, which always works for me, but sometimes when it works for me, I am told it's not externally available and I don't know why, but I'm chalking it up to my router being strangeneillm02:39
Ok, nevermind, I ran it just now:
$ python libbitcoin.py
010000000181d06e4403b989d1e003def4944080e9537ef38e219f58a3856333050d72fe4a080000008b483045022100943e28772ef850587034b447a76c1eb918d63c82a4619a01a34cf32dee13807a02204cbe75c49f8ced0ebc373a6d8e7cb7ecab31369861d8997873b94bac13c379b3014104dbfb10dd8a498b3431f4c7041bbba82aa33146d40b7def4315e9e6df7424d527e762042f9fcc5450cbfc5f849bd3dace5cc9d9b3be8fadc3de92f96e303cf599ffffffff02a8101300000000001976a914b4dc57e35f93de9ec155872c1ad0136134fb08b188acbbe633000000000017a91461ec8bf07c6a3a04a08d1251d70178c1b3d273cc8700000000
neillm02:40
$ cat libbitcoin.py
#!python3
import zmq
import struct
from binascii import hexlify, unhexlify

# Connect to the server.
context = zmq.Context()
socket = context.socket(zmq.REQ)
socket.connect("tcp://mainnet.libbitcoin.net:9091")

# Make the request in parts.
socket.send(b'blockchain.fetch_transaction2', zmq.SNDMORE)
socket.send(struct.pack('I', 42), zmq.SNDMORE)
socket.send(unhexlify('60e030aba2f593caf913a7d96880ff227143bfc370d03dbaee37d582801ebd83')[::-1])

# Collect the response in parts.
response_command = socket.recv()
response_id = socket.recv()
response_body = socket.recv()

# Decode and print transaction from message payload.
print(hexlify(response_body[4:]).decode('ascii'))
🔥 1
C
cguida03:30
Oh, hell yeah, thanks! Yeah the wiki example was the one I tried that didn't work. I'll give this a whirl!
👍 1
neillm00:44
Can you reach the server's port 9091 (e.g. telnet)? That exact code is working for me using both python2 and python3, so I don't think the version is the issue
neillm00:54
Hrm, I'm not sure then. I have had people report connectivity problems to this server in particular in the past even when it was up/responsive to me. Until I can get things moved to another server, I'm not sure what else to try at the moment
Tuesday, January 21, 2025
evoskuil04:30
I've integrated the prevout cache table and running confirmation tests now. This is 1/2 of the two major optimizations that I think will eliminate 32GB machine confirmation thrashing.
Wednesday, January 22, 2025
evoskuil01:42
Running download, validate, confirm on the big box is showing a modest performance benefit (6.5%), which is reasonable since memory is not full yet and even previously the big box does not thrash. This is more of a baseline.
Thursday, January 23, 2025
evoskuil01:26
I realized that I introduced some unrelated code that had a material adverse performance impact, and the need for that code will be going away with the next optimization. My previous benchmark (before the prevout table) didn't have this code. So I'm running it again with that disabled in order to get a better sense of the impact of the prevout table.
evoskuil02:55
It's really interesting to look at the full download/validation/confirmation run in the performance profiler. The building of the prevout table takes .08% of the run. The entire confirmation query takes 1.19% of the run with current optimizations. This is before memory is full, at about 25% of the chain complete. Confirmation is basically free apart from the paging cost.
70% of the run is in script signature validation, 15% is signature hashing (this machine doesn't have shani, otherwise that goes to 3%). 9% is reading blocks and prevouts from the store for validation. 5% is reading blocks off of the wire, hashing, checking and storing.
1 reply · pmienk · last Jan 23, 2025
Huddle with pmienk, cguida, evoskuil, Marnix · 85 min20:54
2 replies · cguida · last Jan 23, 2025
evoskuil22:43
Here's the Parallel Stacks tool I mentioned on the call. This is a deadlock, but the presentation can get far more complex.
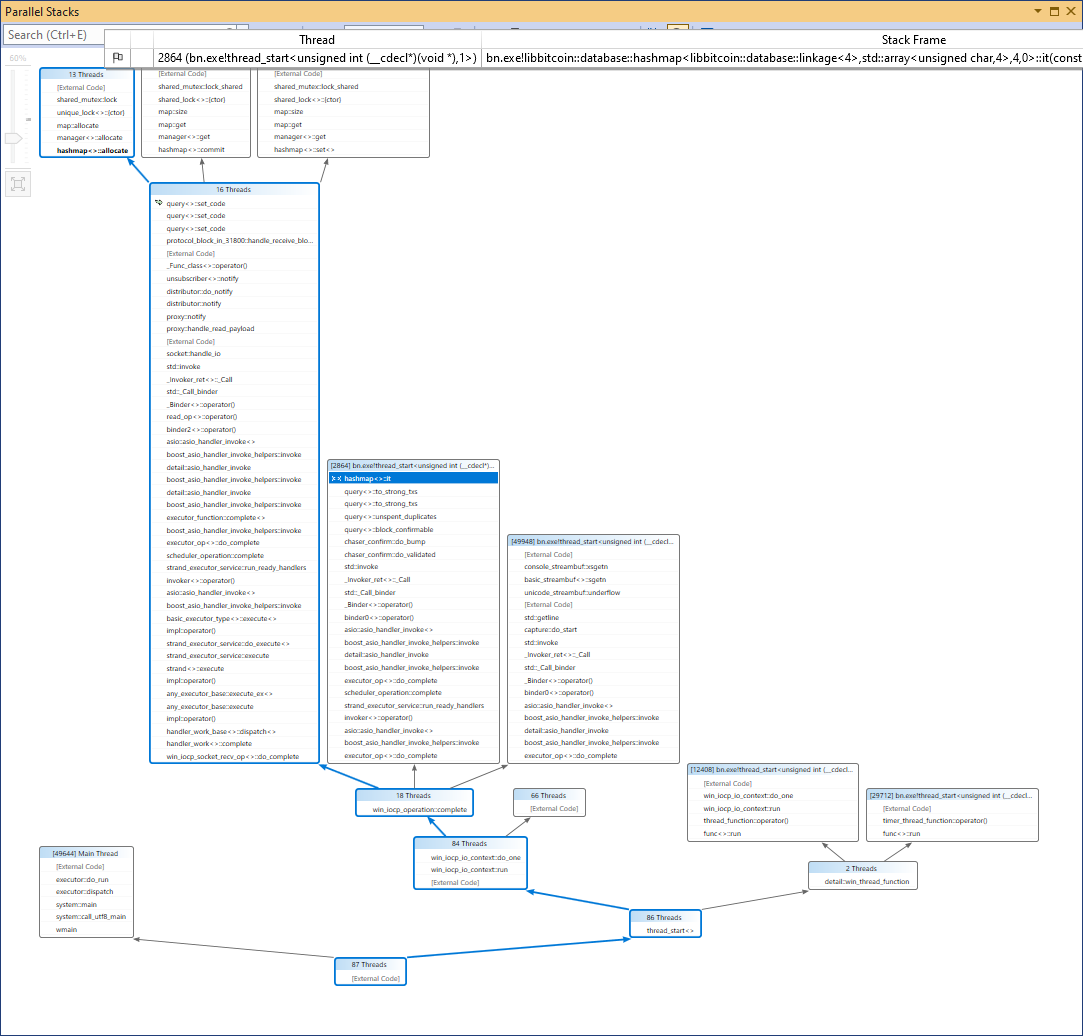
Friday, January 24, 2025
evoskuil00:16
Well I found the reason that I was over-checking bip30. There was a silent hard fork from bitcoin core that disabled bip30 checks based on bip34 activation, and then a more recent silent hard fork that reenables those checks in the future (because the assumption that bip34 made bip30 obsolete was incorrect). In my implementation of these forks recently, I failed to propagate the bip30_deactivate hash in the chain state class. So we've been performing costly unnecessary bip30 checks during confirmation.
👍 1
evoskuil00:32
It goes without saying that chain_state is one of the system classes with insufficient unit test coverage.
Tuesday, January 28, 2025
evoskuil02:18
I spent the past few days tracking down a database primitive (hashmap) regression that I checked in on Wed. One line of code in error, tests were all passing, but this code wasn't being reached. Once I cleaned it up a but more so that each put method called into the next, it was fully covered and exposed the bug. Frustrating few days, but appears to be fully back on track. I should be able to produce metrics on the first part of the confirmation optimization.
👍 1
C
cguida16:53
There don't seem to be any reachable libbitcoin nodes on the network, does that sound correct? https://bitnodes.io/nodes/?q=libbitcoin
evoskuil16:55
Yes, @neillm runs the only libbitcoin v3 nodes I’m aware of. When I test v4 on mainnet I don’t use a libbitcoin user agent string.
(edited)👍 1
evoskuil17:18
Cool, but it’s kind of a vampire node, since it doesn’t yet have an active blocks-out protocol. That could be resolved pretty quickly though. Also, validation and confirmation are undergoing regular changes and have known issues presently, but that can be bypassed (is by default presently).
👍 2

evan17:41
I would also like to run a v4 node 24/7….i am currently running v3 but i just got 2gb fiber so should be able to contribute more
1 reply · neillm · last Jan 28, 2025
evoskuil18:44
Let's give it a few more weeks. Should have something that's pretty stable and with the block-out protocol by then.
(edited)🎉 2
evoskuil19:56
I've completed the default sizing for the new prevout table. At 850k blocks there are
775,526,871 elements in the table. Each element represents a unique block-associated spend (block.tx.input). This includes only spends that are validated, so excludes coinbases, 295k checkpointed blocks, and about 9% block-internal spends (which are statically checked). The total prevout table is 2.9GiB with a 3.2MiB header. The more accurate sizing can now be fed back into default config.Overall the maxi box run with the prevout table used for confirmation query optimization was 5.8% faster than the last run without it. This means that the query improvement outweighs the cost of the additional table. Keep in mind this table is intended to reduce paging and help eliminate thrashing on the mini targets - any improvement on the max is a bonus.
🔥 1
Wednesday, January 29, 2025
evoskuil00:55
@pmienk has updated the minimum compiler versions to clang16/xcode16, gcc12 (and still vc++2022. This allows us to remove hacks for certain C++17 features missing in clang/gcc (
(edited)std::string and std::vector constexpr support, and full std::ranges support).
There is still a lack of support in clang and gcc for parallel execution policy, and there is no projected timeframe for either. Support is present in gcc but requires an external library, is in progress for clang (experimental) and there is no information for xcode. So I've incorporated a single C++ file third party lib under its MIT license, which will give us std:: parallel execution policies for the functions that we use.
Apart from that our last current language workaround is lack of full consteval support (C++20) in clang16. It's supported in xcode16, and clang17 should have it. At that point we'll be clean except for execution policy.👍 3
evoskuil17:22
Another maxi full validation run with the prevouts table and a couple of tweaks, 4.9 hours and 8% faster than baseline (before the changes). Gotta work out one more potential issue and then I'll be consolidating the points table.
👀 1
evoskuil21:42
I'll also give this a go on the mini, though I don't expect confirmation thrashing to be resolved yet.
(edited)Thursday, January 30, 2025
evoskuil03:51
I just performed another maxi box run, but with the new prevout table switched off. This gives the closest possible comparison for the effect of the table. 14.4% faster with the prevout table, which is great.
Huddle with pmienk, evoskuil, Marnix · 122 min20:54
Friday, January 31, 2025
evoskuil16:46
I've fully resolved the issue with the default custom allocator and now have complete runs with both the linear allocator and the default allocator. Issue was lack of deleter invocation in the non-detachable allocator scenario (which only affected use with the default allocator). Performance is similar, with the linear allocator slightly outperforming. Note that the power of the linear allocator is that incoming blocks may be fed across threads without causing a deallocation storm (major performance hit).
This was unrelated to the issue I was dealing with the other day, but I felt it was important to finally figure out what was wrong with the default allocator, since they appeared to be related issues. So everything looking excellent again, trivial fixes in both cases, and some other improvements along the way. Now back to optimizing confirmation.
🔥 1
Here you can see some table flushing, where SSD maxes out for a bit, slows processing, and then both recover.
This is a mini (avx512/shani) milestone run.
evoskuil23:56
60 minutes plus 8 seconds store create, 20 second startup and header sync, and 29 second shutdown.
(edited)